AI Inference Eagle Eye
Feature Introduction
Eagle Eye is an observability system for AI inference scenarios, providing full-link metric collection, near-real-time transmission, intelligent diagnosis, and end-to-end distributed tracing capabilities.
In terms of metric monitoring, it combines Prometheus's periodic metric collection with a distributed message queue system's low-latency push mechanism, achieving comprehensive observability from AI gateway, inference engine, Mooncake to infrastructure (Ray, K8s, hardware). It supports both trend analysis for scaling decisions and the needs of modules with high time-sensitivity requirements (such as intelligent routing) for second-level data updates. Through an independent hardware health diagnosis module, it continuously monitors and identifies anomalies in low-level metrics such as NPU/GPU, temperature, power consumption, and error codes, building a closed-loop monitoring capability of "collection — transmission — diagnosis — assessment".
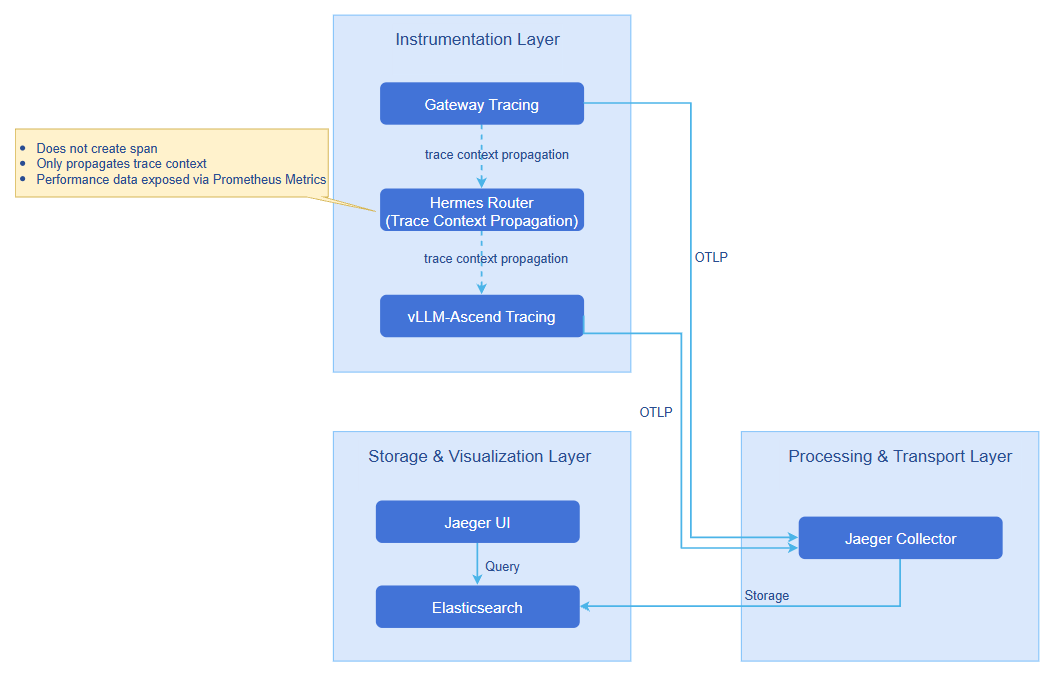
In terms of tracing, based on OpenTelemetry, it provides non-intrusive end-to-end tracing capability, tracking the complete execution path of inference requests from AI gateway to inference engine (vLLM-Ascend), recording the duration and key business attributes of each stage, supporting performance tuning and fault diagnosis.
Application Scenarios
- System Resource Health Monitoring: Real-time monitoring of infrastructure (Ray, K8s, hardware) to ensure the health and stability of system resources, timely detect and resolve resource bottlenecks, and ensure efficient system operation.
- Inference Process Performance Optimization: Real-time monitoring of performance metrics (such as latency, throughput) and resource usage at each stage of the inference process (such as prefill, decode), identifying and analyzing performance bottlenecks, optimizing model execution efficiency, and improving the response speed and computational efficiency of inference tasks.
- Hardware Fault Diagnosis and Repair: View anomaly analysis reports provided by the hardware diagnosis module, which include fault pattern identification and remediation suggestions, helping to quickly locate and resolve hardware faults. The system can monitor hardware status such as NPU/GPU, temperature, and power consumption in real time, generate detailed fault analysis reports, provide specific fault causes and repair solutions, and ensure hardware stability and reliability.
- Automatic Scaling Decisions: Obtain SLA-related metrics (such as throughput rate, latency, etc.) and use this data as the basis for automatic scaling decisions, ensuring that inference services dynamically expand or shrink based on load and performance requirements, achieving the goal of elastic scaling.
- Intelligent Routing Decisions: Achieve near-real-time data updates through a distributed message queue system, enabling intelligent routing to make decisions quickly based on the latest data, thereby optimizing response speed during AI inference.
- Weight Distribution Acceleration Decisions: Achieve near-real-time data transmission through a distributed message queue system, obtaining real-time network dynamic performance metrics (such as actual transmission rate of node RDMA NICs, remaining available bandwidth, etc.), combined with static metrics (such as theoretical transmission speed of node RDMA NICs, NIC PCIe bandwidth, etc.) attached to nodes as labels by NPU Feature Discovery. Based on these metrics, the module dynamically evaluates node performance and ultimately selects the node with optimal performance for task assignment, thereby ensuring optimal resource utilization and maximizing system stability and processing efficiency.
- Inference Request Fault Quick Localization: When inference requests encounter issues such as slow response, timeout, or failure, view the complete call chain through the Jaeger UI to quickly locate whether the bottleneck is at the AI gateway, routing decision, or a specific stage of the inference engine. Analyze the duration and key attributes of each stage (KVCache hit rate, inference execution duration, TTFT (Time to First Token) / ITL (Inter-Token Latency) and other performance metrics) to precisely identify the root cause of the fault.
Capability Scope
- Multi-layer Metric Coverage: Covers AI gateway (such as performance, resource consumption, security and compliance audit, governance policy execution records), inference engine (API Server, model input/output, inference process, inference engine status), Mooncake (Mooncake master, transfer engine, Mooncake client), and infrastructure (Ray, K8s, hardware), achieving full-link observability.
- Near-real-time Metric Transmission: For modules with high time-sensitivity requirements, achieves second-level metric push through a distributed message queue system, ensuring that metrics can be promptly perceived and influence decisions.
- Scaling Decision Support: Synchronously reports collected system and runtime metrics to Prometheus for periodic computation and trend evaluation.
- Hardware Health Check and Diagnosis: Builds an independent hardware health diagnosis module that periodically collects low-level metrics such as NPU/GPU temperature, power consumption, and error codes, and reports them in real time through a distributed message queue system. The diagnosis module subscribes to and analyzes the collected data, combining device model, driver, and firmware information, and based on threshold rules and anomaly metric analysis, identifies typical fault patterns and outputs diagnostic conclusions and remediation suggestions, achieving a closed loop from data collection to health assessment.
- End-to-end Distributed Tracing: Based on the OpenTelemetry standard, provides non-intrusive request-level tracing capability from AI gateway to inference engine (vLLM-Ascend), supporting collection, storage, and querying, recording key performance metrics and business attributes.
Implementation Principle
Metric Monitoring
Logical View
Figure 1 Level-0 Logical View
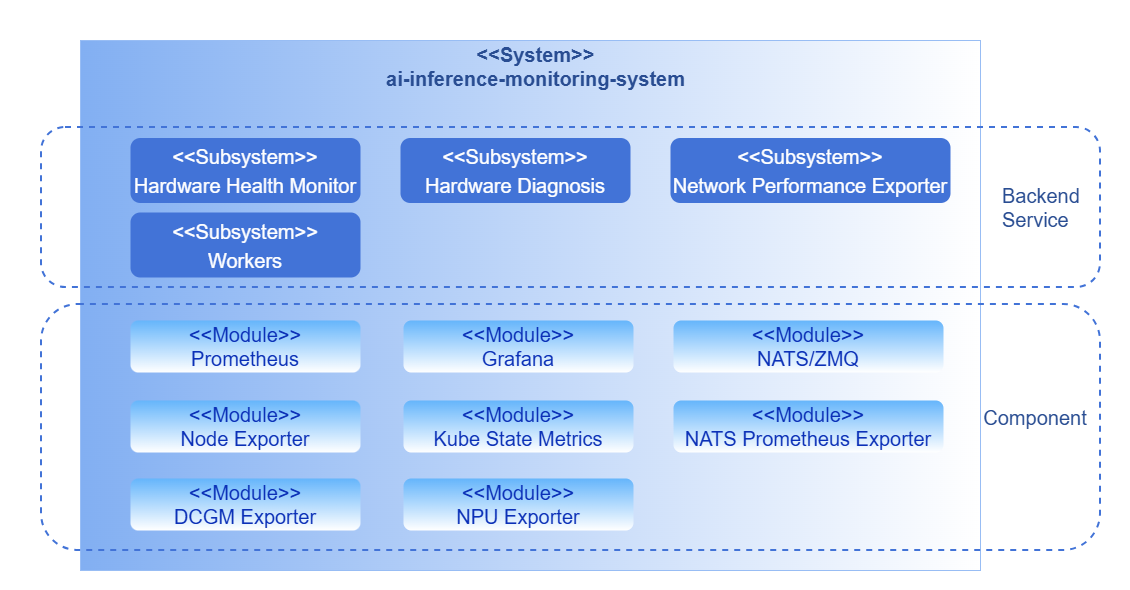
The monitoring system is divided into backend layer and component layer by business hierarchy.
Backend Layer
- Hardware Health Monitor: The hardware health monitoring module, as an independently running collection component, actively executes metric collection and reporting as periodic tasks. During operation, the module calls low-level interfaces (DCMI, NVML) or parses system logs (dmesg) at fixed collection intervals to obtain device running status and health information. Collection results are published in real time to the diagnosis module through a distributed message queue system, achieving decoupling of collection and diagnosis.
- Hardware Diagnosis: The diagnosis module subscribes to metric data published by the collection module through a distributed message queue system, combining device model, driver, and firmware information to perform real-time analysis of hardware health status. The module supports threshold judgment and anomaly detection, identifies typical fault patterns, and outputs diagnostic conclusions and remediation suggestions, achieving a closed loop from data collection to health assessment.
Component Layer
The component layer provides underlying metric collection, transmission, and presentation capabilities, covering the following key modules: metric collection (Exporter), high-performance distributed message queue system, metric storage (Prometheus), and presentation (Grafana).
Data Flow Diagram
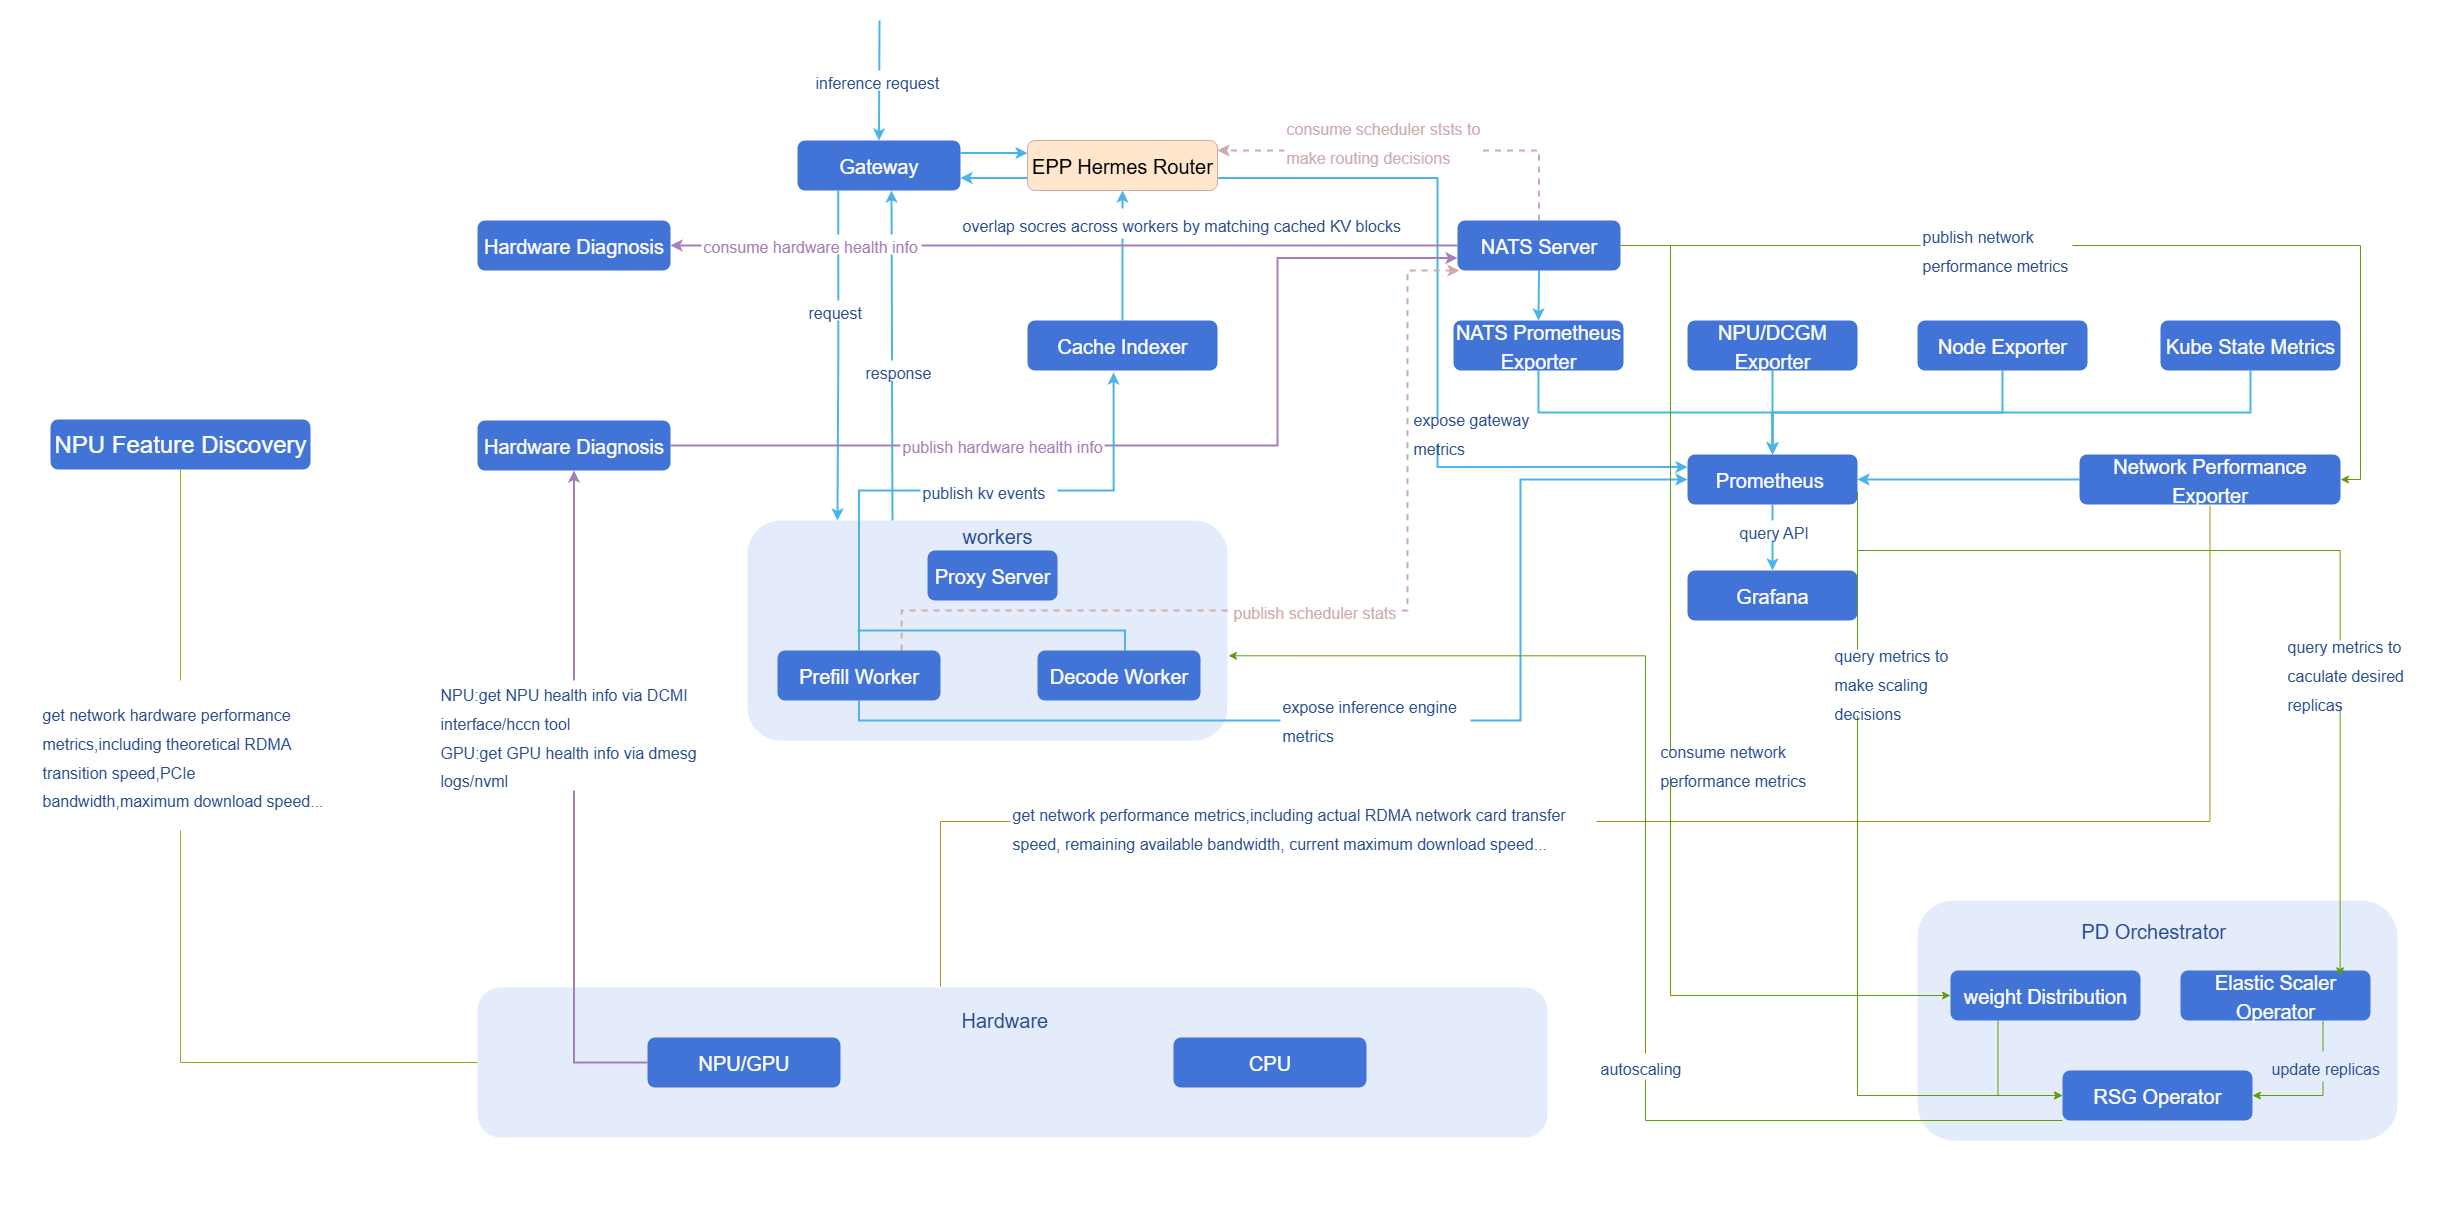
NATS
Figure 2 Data Flow Diagram - NATS
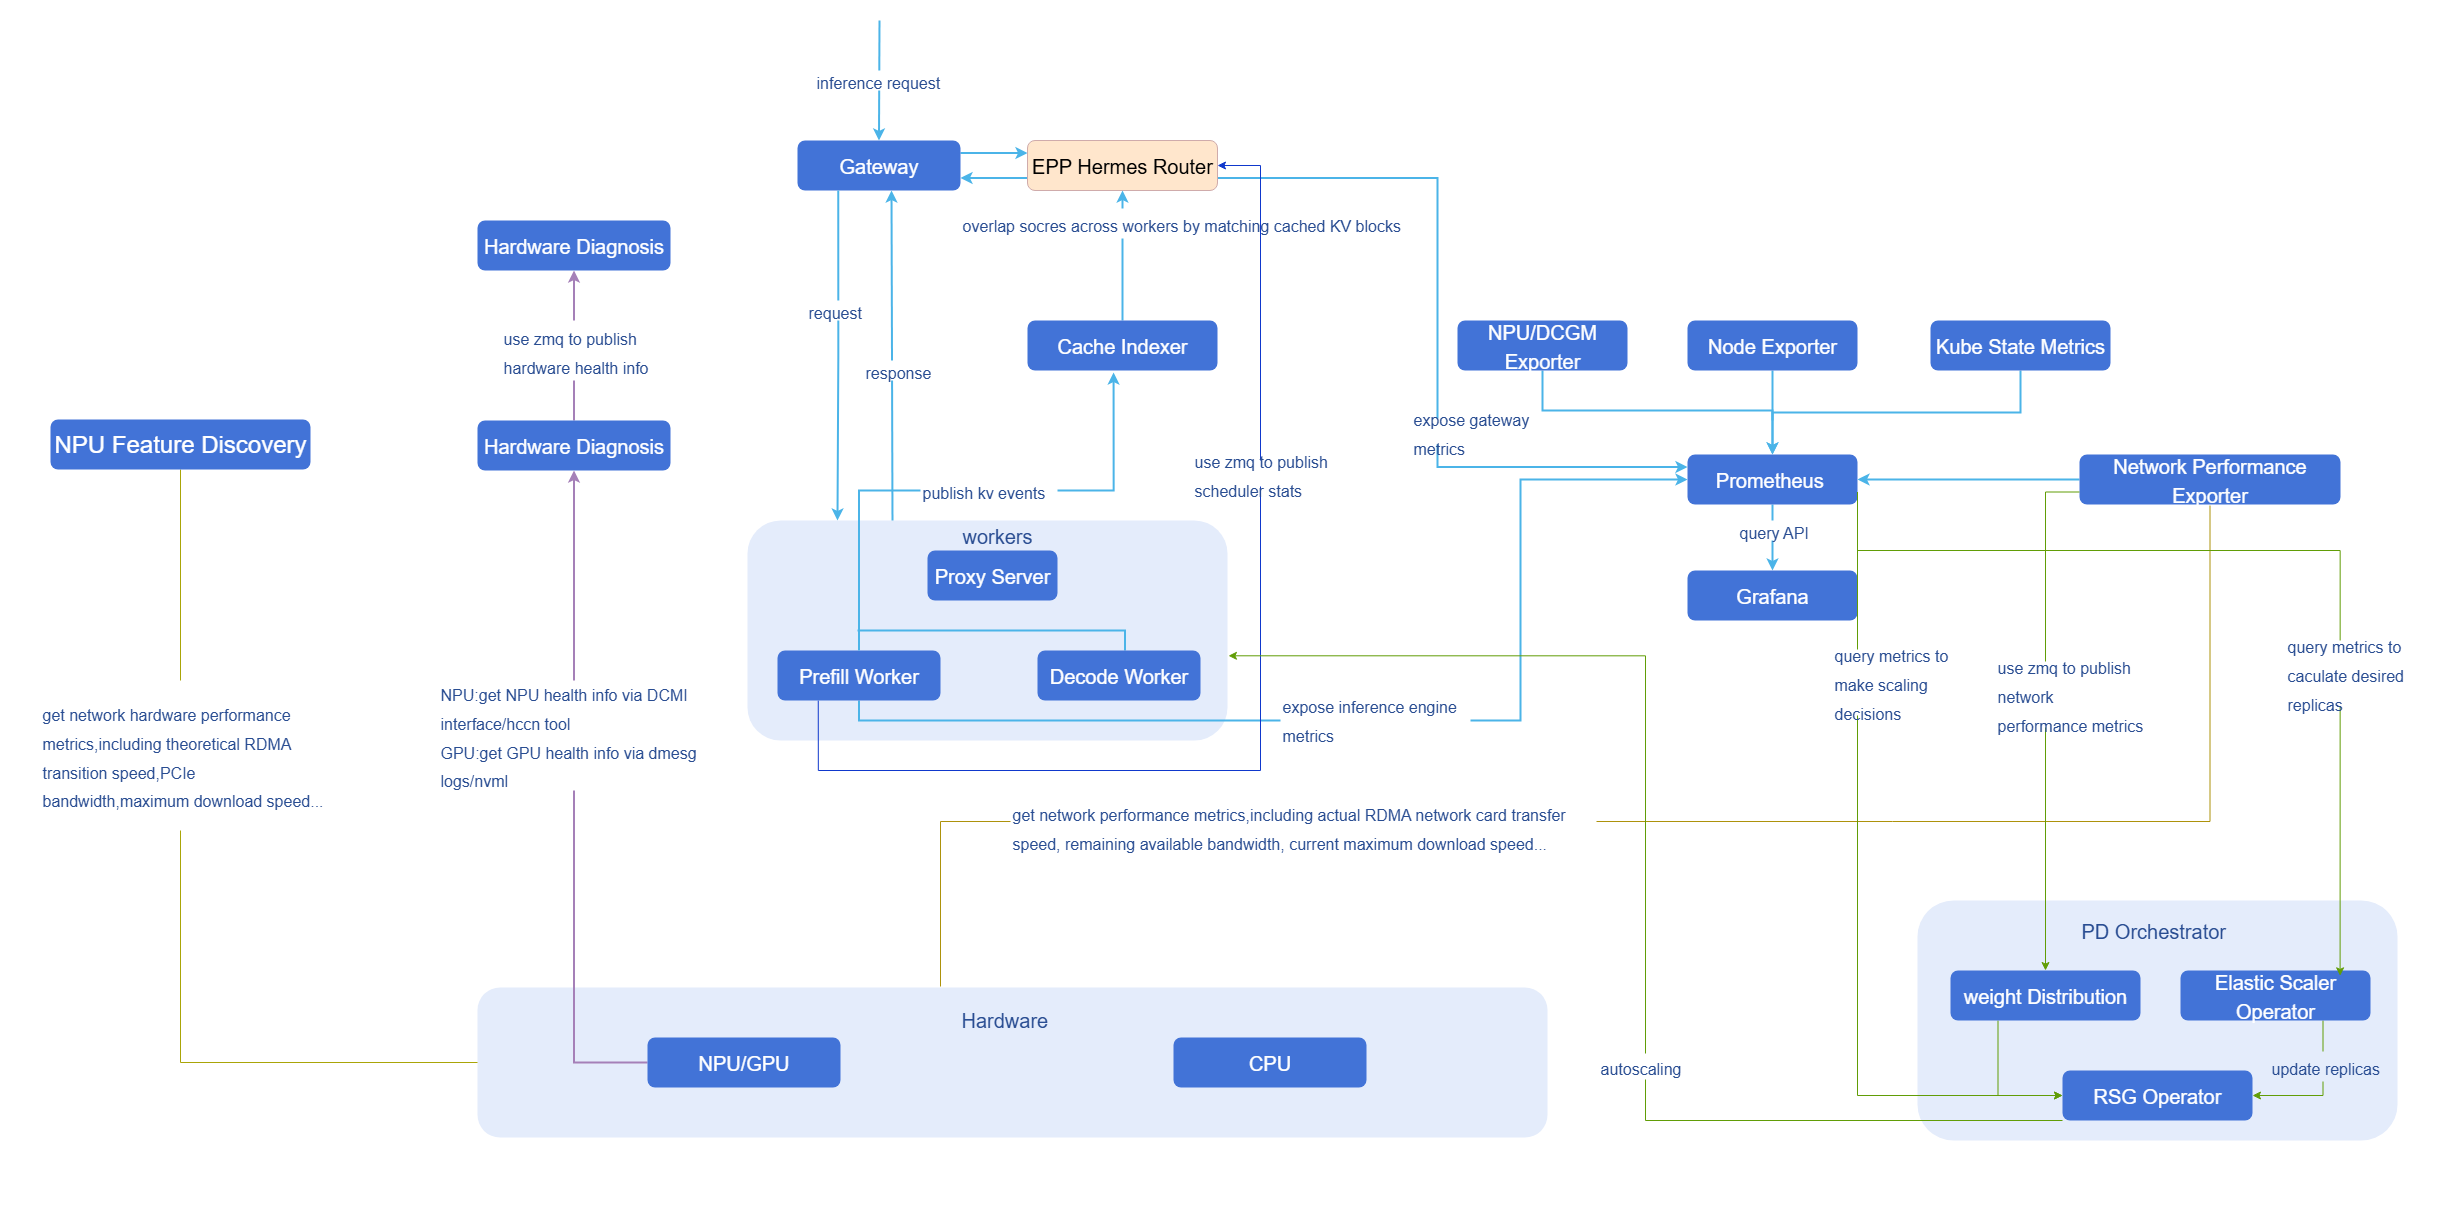
ZMQ
Figure 3 Data Flow Diagram - ZMQ
Full Data List
Table 1 Full Data List
| Observability Dimension | Observability Category | Observability Item | Observability Sub-item | Specific Metric | Static/Dynamic | Metric Source | Real-time Requirement | Metric Transport | Currently Supported | Remarks |
| AI Gateway | Performance | - | - | QPS | Dynamic | EPP | Low | Prometheus | - | - |
| Request success rate | - | |||||||||
| Overall latency of non-streaming response | - | |||||||||
| First packet latency of streaming response (TTFT) | - | |||||||||
| Resource Consumption | - | - | Token consumption count/s | Dynamic | EPP | Low | Prometheus | Large model services billed by token | ||
| Token usage statistics by model dimension | EPP | |||||||||
| Token usage statistics by user dimension | - | |||||||||
| Security and Compliance Audit | - | - | Content security interception logs | Dynamic | - | Low | Prometheus | - | ||
| Risk type statistics | - | - | ||||||||
| Risk user statistics | - | - | ||||||||
| Governance Policy Execution Records | - | - | Rate limiting statistics | - | Low | Prometheus | - | |||
| Cache hit status | EPP | - | ||||||||
| Fallback success rate | - | - | ||||||||
| Inference Engine | API Server | - | - | Path | Dynamic | - | Low | Prometheus | - | - |
| Status code | - | |||||||||
| Client | - | |||||||||
| Duration | - | |||||||||
| Model Input/Output | - | - | Prompt | Static | - | Low | Prometheus | ✅ | Exposed as OpenTelemetry Trace attributes; needs to be enabled when deploying vLLM. vllm serve your-model --otlp-traces-endpoint="http://your-collector:4317" --collect-detailed-traces=all | |
| Response mode | - | |||||||||
| Model name | vLLM | |||||||||
| Max token count | vLLM | |||||||||
| Temperature | vLLM | |||||||||
| top-k | - | |||||||||
| top-p | vLLM | |||||||||
| N | vLLM | |||||||||
| Inference Process | - | - | E2E time | Dynamic | vLLM | Low | Prometheus | - | ||
| TTFT | - | |||||||||
| Prefill time | - | |||||||||
| Decode time | - | |||||||||
| Time request waits in scheduler | - | |||||||||
| Token interval time | - | |||||||||
| Inference Engine Status | - | - | Running request count | Dynamic | vLLM | Low | Prometheus | - | ||
| Waiting request count | - | |||||||||
| Preempted request count | - | |||||||||
| KV cache usage rate | - | |||||||||
| Total prompt token count | - | |||||||||
| Total generated token count | - | |||||||||
| Successfully processed request count | - | |||||||||
| Mooncake | Mooncake master | - | - | - | Dynamic | Mooncake | Low | Prometheus | - | Mooncake master exposes metrics directly to Prometheus via /metrics, while transfer engine and Mooncake client metrics are recorded in logs. |
| transfer engine | - | - | - | Dynamic | Low | Prometheus | ||||
| Mooncake client | - | - | - | Dynamic | Low | Prometheus | ||||
| Infrastructure | ray | - | - | - | Dynamic | ray | Low | Prometheus | - | - |
| kubernetes | Cluster health | - | - | Dynamic | kube-state-metrics/node-exporter | Low | Prometheus | ✅ | - | |
| Resource usage | - | - | - | |||||||
| Workload status | - | - | - | |||||||
| Scheduling and Elasticity | Scheduling | Scheduling queue | kube-scheduler | Prometheus | ✅ | - | ||||
| Scheduling latency | - | |||||||||
| Scheduling success/failure rate | - | |||||||||
| Retry count | - | |||||||||
| Elasticity | Desired replica count | kube-state-metrics | Prometheus | ✅ | - | |||||
| Current replica count | - | |||||||||
| Ready replica count | - | |||||||||
| Scaling latency | - | - | - | |||||||
| Image pull time | kubelet | ✅ | - | |||||||
| Weight download time | - | - | - | |||||||
| Scaling trigger count | - | - | - | |||||||
| Hardware | Compute Resources | - | machine_npu_nums | Dynamic | npu-exporter | Low | Prometheus | ✅ | - | |
| npu_chip_info_utilization | - | |||||||||
| npu_chip_info_overall_utilization | - | |||||||||
| npu_chip_info_vector_utilization | - | |||||||||
| npu_chip_info_temperature | - | |||||||||
| npu_chip_info_power | - | |||||||||
| npu_chip_info_voltage | - | |||||||||
| npu_chip_info_aicore_current_freq | - | |||||||||
| npu_chip_info_process_info_num | - | |||||||||
| npu_chip_info_process_info | - | |||||||||
| container_npu_utilization | - | |||||||||
| container_npu_total_memory | - | |||||||||
| container_npu_used_memory | - | |||||||||
| Memory and HBM | hbm (910A1/910A2/910A3/910A5) | npu_chip_info_hbm_used_memory | - | |||||||
| npu_chip_info_hbm_total_memory | - | |||||||||
| npu_chip_info_hbm_utilization | - | |||||||||
| npu_chip_info_hbm_temperature | - | |||||||||
| npu_chip_info_hbm_bandwidth_utilization | - | |||||||||
| npu_chip_info_hbm_ecc_enable_flag | - | |||||||||
| npu_chip_info_hbm_ecc_single_bit_error_cnt | - | |||||||||
| npu_chip_info_hbm_ecc_double_bit_error_cnt | - | |||||||||
| npu_chip_info_hbm_ecc_total_single_bit_error_cnt | - | |||||||||
| npu_chip_info_hbm_ecc_total_double_bit_error_cnt | - | |||||||||
| npu_chip_info_hbm_ecc_single_bit_isolated_pages_cnt | - | |||||||||
| npu_chip_info_hbm_ecc_double_bit_isolated_pages_cnt | - | |||||||||
| ddr (except 910A2/910A3/910A5) | npu_chip_info_total_memory | - | ||||||||
| npu_chip_info_used_memory | - | |||||||||
| Interconnect and IO | network (except 310/310B/310P) | npu_chip_info_bandwidth_tx | - | |||||||
| npu_chip_info_bandwidth_rx | - | |||||||||
| npu_chip_link_speed | - | |||||||||
| npu_chip_link_up_num | - | |||||||||
| pcie (910A2) | npu_chip_info_pcie_rx_p_bw | - | ||||||||
| npu_chip_info_pcie_rx_np_bw | - | |||||||||
| npu_chip_info_pcie_rx_cpl_bw | - | |||||||||
| npu_chip_info_pcie_tx_p_bw | - | |||||||||
| npu_chip_info_pcie_tx_np_bw | - | |||||||||
| npu_chip_info_pcie_tx_cpl_bw | - | |||||||||
| hccs (910A2/910A3) | npu_chip_info_hccs_statistic_info_tx_cnt_index | - | ||||||||
| npu_chip_info_hccs_statistic_info_rx_cnt_index | - | |||||||||
| npu_chip_info_hccs_statistic_info_crc_err_cnt_index | - | |||||||||
| npu_chip_info_hccs_bandwidth_info_tx_index | - | |||||||||
| npu_chip_info_hccs_bandwidth_info_rx_index | - | |||||||||
| npu_chip_info_hccs_bandwidth_info_profiling_time | - | |||||||||
| npu_chip_info_hccs_bandwidth_info_total_tx | - | |||||||||
| npu_chip_info_hccs_bandwidth_info_total_rx | - | |||||||||
| roce (except 310/310B/310P) | npu_chip_mac_rx_pause_num | - | ||||||||
| npu_chip_mac_tx_pause_num | - | |||||||||
| npu_chip_mac_rx_pfc_pkt_num | - | |||||||||
| npu_chip_mac_tx_pfc_pkt_num | - | |||||||||
| npu_chip_mac_rx_bad_pkt_num | - | |||||||||
| npu_chip_mac_tx_bad_pkt_num | - | |||||||||
| npu_chip_mac_tx_bad_oct_num | - | |||||||||
| npu_chip_mac_rx_bad_oct_num | - | |||||||||
| npu_chip_info_rx_fcs_num | - | |||||||||
| npu_chip_info_rx_ecn_num | - | |||||||||
| npu_chip_roce_rx_all_pkt_num | - | |||||||||
| npu_chip_roce_tx_all_pkt_num | - | |||||||||
| npu_chip_roce_rx_err_pkt_num | - | |||||||||
| npu_chip_roce_tx_err_pkt_num | - | |||||||||
| npu_chip_roce_rx_cnp_pkt_num | - | |||||||||
| npu_chip_roce_tx_cnp_pkt_num | - | |||||||||
| npu_chip_roce_new_pkt_rty_num | - | |||||||||
| npu_chip_roce_out_of_order_num | - | |||||||||
| npu_chip_roce_qp_status_err_num | - | |||||||||
| npu_chip_roce_unexpected_ack_num | - | |||||||||
| npu_chip_roce_verification_err_num | - | |||||||||
| Network Hardware Performance | - | Node RDMA NIC theoretical bandwidth upper limit | Static | npu-feature-discovery | Low | / | ✅ | - | ||
| Node RDMA NIC PCIe bandwidth | ||||||||||
| NPU card-side RoCE NIC total bandwidth | ||||||||||
| - | Node RDMA NIC link status | Dynamic | network-performace-exporter | High | Prometheus NATS/ZMQ | ✅ | - | |||
| Node RDMA NIC physical link status | ||||||||||
| Node RDMA NIC cumulative sent traffic | ||||||||||
| Node RDMA NIC cumulative received traffic | ||||||||||
| Node RDMA NIC actual send rate | ||||||||||
| Node RDMA NIC actual receive rate | ||||||||||
| Node RDMA NIC remaining bandwidth in send direction | ||||||||||
| Node RDMA NIC remaining bandwidth in receive direction | ||||||||||
| NPU card-side RoCE NIC physical link status | ||||||||||
| NPU card-side RoCE NIC physical link UP count | ||||||||||
| NPU card-side RoCE NIC actual send rate | ||||||||||
| NPU card-side RoCE NIC actual receive rate | ||||||||||
| NPU card-side RoCE NIC remaining bandwidth in send direction | ||||||||||
| NPU card-side RoCE NIC remaining bandwidth in receive direction | ||||||||||
| NPU card-side RoCE NIC packet loss rate | ||||||||||
| NPU card-side RoCE NIC retransmission rate | ||||||||||
| Hardware Health | Black box error code | - | Dynamic | eagle-eye-hardware-monitor | High | NATS/ZMQ | ✅ | - | ||
| Health management fault code | - | - | ||||||||
| hbm (910A1/910A2/910A3/910A5) | npu_chip_info_hbm_temperature | - | ||||||||
| npu_chip_info_hbm_total_memory | - | |||||||||
| npu_chip_info_hbm_used_memory | - | |||||||||
| npu_chip_info_hbm_memory_utilization | - | |||||||||
| ddr (except 910A2/910A3/910A5) | npu_chip_info_memory_utilization | - | ||||||||
| network (except 310/310B/310P) | npu_chip_info_link_status | - | ||||||||
| npu_chip_info_bandwidth_rx | - | |||||||||
| npu_chip_info_bandwidth_tx | - | |||||||||
| Hardware Status | npu_chip_info_power | NPU overload frequency reduction | ||||||||
| npu_chip_info_aicore_freq | ||||||||||
| npu_chip_info_aicore_current_freq | ||||||||||
| npu_chip_info_temperature | ||||||||||
| npu_chip_info_network_status | - | |||||||||
| npu_chip_info_health_status | - |
Notice: network performance exporter, hardware monitor, hardware diagnosis, and npu exporter all need to enable privileged containers during deployment; otherwise, DCMI cannot be loaded, resulting in data not being correctly collected.
End-to-End Tracing
Logical View
Figure 4 Level-0 Logical View
vLLM-Ascend Span Structure
vllm_ascend.request (API process - full request lifecycle)
├─ vllm_ascend.prefill_execution (API process - Prefill phase, created post-hoc)
│  ├─ vllm_ascend.prefill.schedule (Prefill scheduling aggregate statistics, created post-hoc)
│  ├─ vllm_ascend.prefill.kv_cache (Prefill allocation aggregate statistics, created post-hoc)
│  └─ vllm_ascend.prefill.ascend_store (AscendStore save operation, created post-hoc)
└─ vllm_ascend.decode_phase (API process - Decode phase, created post-hoc)
 ├─ vllm_ascend.decode.schedule (Decode scheduling aggregate statistics, created post-hoc)
 ├─ vllm_ascend.decode.kv_cache (Decode allocation aggregate statistics, created post-hoc)
vLLM-Ascend Span Description
Table 2 vLLM-Ascend Span Description Table
| Span Name | Parent Span | Key attributes |
|---|---|---|
vllm_ascend.request | None | request.request_idrequest.temperature request.top_p request.max_tokens request.nrequest.latency.e2erequest.latency.time_in_queuerequest.latency.time_to_first_tokenrequest.usage.prompt_tokensrequest.usage.completion_tokens |
vllm_ascend.prefill_execution | request | prefill.num_tokensprefill.total_time_ms |
vllm_ascend.prefill.schedule | prefill_execution | schedule.total_callsschedule.total_tokensschedule.avg_tokens_per_callschedule.total_time_msschedule.avg_time_msschedule.avg_queue_lengthschedule.max_queue_lengthschedule.avg_running_count |
vllm_ascend.prefill.kv_cache | prefill_execution | kv_cache.total_callskv_cache.total_blocks_allocatedkv_cache.avg_blocks_per_callkv_cache.final_free_blockskv_cache.total_cached_tokenskv_cache.cache_hit_ratekv_cache.num_external_computed_tokenskv_cache.has_external_cache |
vllm_ascend.prefill.ascend_store | prefill_execution | store.operationstore.save_duration_msstore.status |
vllm_ascend.decode_phase | request | decode.num_iterationsdecode.total_time_msdecode.avg_time_per_token_msdecode.max_time_per_token_ms |
vllm_ascend.decode.schedule | decode_phase | schedule.total_callsschedule.total_time_msschedule.avg_time_msschedule.max_time_msschedule.avg_queue_lengthschedule.max_queue_lengthschedule.avg_running_count |
vllm_ascend.decode.kv_cache | decode_phase | kv_cache.total_callskv_cache.total_blocks_allocatedkv_cache.avg_blocks_per_callkv_cache.final_free_blockskv_cache.min_free_blockskv_cache.avg_free_blockskv_cache.total_preemptionskv_cache.preemption_rate |
Relationship with Related Features
- Tracing: Depends on the inference engine (e.g., vLLM-Ascend 0.18.0).
Installation
Prerequisites
Hardware Requirements
Eagle Eye itself has no special hardware environment requirements.
Software Requirements
Kubernetes v1.33.0 or above.
Starting Installation
openFuyao Platform
Log in to the openFuyao management plane.
Select "Application Market > Application List" from the left navigation bar to navigate to the "Application List" page.
Check "Artificial Intelligence/Machine Learning" under "Scenarios" on the left, and find the "eagle-eye" card. Or enter "eagle-eye" in the search box.
Click "Deploy" to enter the "Deploy" page.
Enter the application name, select the installation version and namespace. You can choose an existing namespace or create a new one; for creating a namespace, see Namespace.
Configure eagle-eye in the "values.yaml" under parameter configuration.
Notice:networkPerformanceExporter.collectIntervalis used to configure the network-performance-exporter collection interval (in seconds), with a default value of 15s. If this value is set too short, it may cause the next collection round to be triggered before the previous one completes, resulting in incomplete metric data. It is recommended not to go below the default value of 15s.Click "Deploy" to complete the installation.
Standalone Deployment
In addition to openFuyao platform installation and deployment, this feature also provides standalone deployment functionality through the following two methods:
- Obtain the project installation package from the openFuyao official image repository.
Execute the following command to pull the project installation package.
helm pull oci://cr.openfuyao.cn/charts/eagle-eye --version xxxWhere
xxxneeds to be replaced with the specific project installation package version, such as0.0.0-latest. The obtained installation package is in compressed package form.Execute the following command to extract the installation package.
cdtar -zxvf eagle-eyeInstall and deploy.
Execute the following command in the same directory as eagle-eye.
helm install eagle-eye -n xxxxxx .
- Obtain from the openFuyao GitCode repository.
Execute the following command to pull the project from the repository.
git clone https://gitcode.com/openFuyao/eagle-eye.gitInstall and deploy. Execute the following command in the same directory as eagle-eye.
helm install eagle-eye -n xxxxxx .
Using Metric Monitoring
High Real-time Metric Collection and Reporting for Intelligent Routing
NATS
To meet the high time-sensitivity requirements of modules such as intelligent routing, the system uses NATS for second-level push of key performance metrics. This enables metrics such as waiting request count and NPU/GPU KVCache utilization to be perceived in real time, thereby dynamically adjusting decisions.
Currently only vLLM deployment is supported.
Prerequisites
- Kubernetes cluster is deployed and accessible.
kubectlcommand-line tool is installed with cluster access permissions configured.- Ascend driver and related dependencies are installed on the nodes.
- NATS is deployed and running normally.
Deployment Steps
The NATS publish/subscribe model is selected as the metric transmission method. CustomStatLogger is a custom statistics data logger implemented in vLLM by inheriting from the StatLoggerBase abstract class. As a publisher, CustomStatLogger actively generates structured runtime metric messages after each decode batch ends and publishes them to the specified NATS topic; Router as a subscriber only needs to register a listener on that topic to receive messages the moment they are published and trigger subsequent processing logic.
To avoid losing the first batch of messages, the subscriber (Router) must complete connection and subscription before the publisher (CustomStatLogger).
Router (Subscriber).
Routeras a subscriber is mainly responsible for receiving published runtime metric messages and triggering corresponding processing logic. Refer to the following code example to implementRouterand deploy it to the Kubernetes cluster.import logging import json from nats.aio.client import Client as NATS_Client logger = logging.getLogger() class RouterSubscriber: def __init__(self, server_address: str, topic: str): """ Initialize RouterSubscriber instance :param server_address: NATS server address :param topic: Topic to subscribe to """ self.server_address = server_address self.topic = topic self.client = NATS_Client() async def connect(self): """ Establish connection with NATS server """ try: # Establish NATS persistent connection await self.client.connect(self.server_address) logger.info("Connected to NATS server at %s", self.server_address) except Exception as e: logger.error("Failed to connect to NATS server: %s", e) raise e async def subscribe(self, topic: str, message_handler): """ Subscribe to the specified topic and pass received messages to business logic processing :param message_handler: Business logic processing function for handling received messages """ try: async def on_message(msg): """ Message callback function, handles subscribed messages :param msg: NATS message """ logger.info("Received message on topic %s", topic) await message_handler(msg) # Ensure NATS connection if not self.client.is_connected: await self.connect() # Register subscription topic and bind message callback function await self.client.subscribe(topic, cb=on_message) logger.info("Successfully subscribed to NATS topic %s", topic) except Exception as e: logger.error("Failed to subscribe to NATS topic %s: %s", topic, e) raise e async def message_handler(self, msg) -> None: """ NATS raw callback, responsible for: 1. Decoding data from msg; 2. Calling parse_message for JSON deserialization; 3. Passing parsed structured data to subsequent business logic processing. """ try: data = msg.data.decode("utf-8") except Exception as exc: logger.error("Failed to decode NATS message: %s", exc) return data_dict = self.parse_message(data) if not data_dict: # Return directly on parse failure to avoid subsequent logic exceptions return # TODO: Handle specific business logic here, e.g., make routing decisions based on metrics ... def parse_message(self, data: str) -> Dict[str, Any]: """ Deserialize NATS message body from JSON string to dictionary. Logs and returns empty dictionary on parse failure. """ try: return json.loads(data) except Exception as exc: logger.error("Failed to parse message: %s, raw: %r", exc, data) return {}Customstatlogger (Publisher).
CustomStatLoggeris the publisher, responsible for generating and publishing real-time runtime metric data. After each decode batch ends,CustomStatLoggerpublishes structured metric messages to the specified NATS topic (this topic should match the subscriber's topic, currentlyeagle_eye.routing_metrics) forRouterto subscribe.2.1 Package source code.
Execute the following command in the project root directory to package the source code into a compressed file.
bashtar -czf source_code.tar.gz src/ requirements.txt2.2 Create ConfigMap.
Import the compressed package as a binary file into a ConfigMap.
bash# Check if namespace exists, create it if not kubectl get namespace ai-inference || kubectl create namespace ai-inference # If a ConfigMap with the same name already exists, delete it first kubectl delete configmap vllm-source-code -n ai-inference --ignore-not-found # Create new ConfigMap kubectl create configmap vllm-source-code \ --from-file=source_code.tar.gz=source_code.tar.gz \ -n ai-inference2.3 Deploy the service.
Apply the deployment YAML file.
bashkubectl apply -f ./docs/routing-metrics/vllm_eagle_eye.yaml2.4 Check deployment status.
bash# View Pod running status kubectl get pods -n ai-inference -l app=vllm-eagle-eye # View Pod details kubectl describe pod -n ai-inference -l app=vllm-eagle-eye # View Pod logs kubectl logs -n ai-inference -l app=vllm-eagle-eye -fVerification steps.
3.1 Method 1: Verify using a temporary Pod.
3.1.1 Get the service Pod IP address.
bashkubectl get pod -n ai-inference -l app=vllm-eagle-eye -o wideRecord the
IPaddress from the output (e.g.,10.244.1.5).3.1.2 Start a temporary test Pod.
bashkubectl run curl-test --image=curlimages/curl -n ai-inference -it --rm --restart=Never -- sh3.1.3 Send a test request from the temporary Pod.
Execute in the temporary Pod's shell (replace
<POD_IP>with the actual IP address):bashcurl -X POST http://<POD_IP>:8000/generate \ -H "Content-Type: application/json" \ -d '{"prompt": "Hello AI"}'3.2 Method 2: Verify using port-forward.
bash# Port forwarding kubectl port-forward -n ai-inference deployment/vllm-eagle-eye 8000:8000 # Send request from another terminal curl -X POST http://localhost:8000/generate \ -H "Content-Type: application/json" \ -d '{"prompt": "Hello AI"}'Clean up resources.
bash# Delete Deployment kubectl delete -f ./docs/routing-metrics/vllm_eagle_eye.yaml # Delete ConfigMap kubectl delete configmap vllm-source-code -n ai-inference # Delete temporary Pod kubectl delete pod -n ai-inference curl-test
Common Issues
Pod fails to start.
bash# View Pod events kubectl describe pod -n ai-inference -l app=vllm-eagle-eye # View init container logs kubectl logs -n ai-inference <pod-name> -c code-extractorDependency installation failure.
If the cluster cannot access the internet, dependencies need to be pre-packaged.
bash# Download dependencies locally pip download -r requirements.txt -d packages/ # Include dependencies when packaging tar -czf source_code.tar.gz src/ requirements.txt packages/
Using Tracing
vLLM-Ascend Trace Data Reporting Configuration
Eagle Eye automatically installs tracing backend components (Jaeger + Elasticsearch) when deployed via Helm Chart. Users need to configure the OTLP reporting address on the inference engine side to report Trace data to Eagle Eye's Jaeger.
Prerequisites
- Kubernetes cluster is deployed and accessible.
kubectlcommand-line tool is installed with cluster access permissions configured.- Ascend driver and related dependencies are installed on the nodes.
- Eagle Eye has been successfully deployed via Helm Chart (Eagle Eye tracing backend is enabled by default, including Jaeger and Elasticsearch).
- The inference engine is vLLM-Ascend.
Deployment Steps
Get the Jaeger service address.
bashkubectl get svc -n <release-namespace> | grep eagle-eye-tracing-collectorRecord the Jaeger Collector service port (default OTLP/gRPC port is
4317).Modify vLLM-Ascend deployment configuration.
Add tracing-related configuration to the vLLM-Ascend deployment configuration, including initContainers, environment variables, startup parameters, volume mounts, etc.
Complete example (replace placeholders with actual values):
yamlapiVersion: apps/v1 kind: Deployment metadata: name: vllm-ascend namespace: ai-inference spec: template: spec: # initContainer: copy tracing files to shared directory initContainers: - name: install-tracing image: cr.openfuyao.cn/openfuyao/eagle-eye-tracing:latest imagePullPolicy: IfNotPresent command: ["cp", "-r", "/tracing-source/.", "/tracing-install/"] volumeMounts: - name: tracing-install mountPath: /tracing-install containers: - name: vllm image: <your-vllm-ascend-image>:<tag> imagePullPolicy: IfNotPresent command: ["/bin/bash", "-c"] args: - | set -euo pipefail # Install tracing files to Python environment /tracing-install/install.sh # Other initialization commands... # Start vLLM, add --otlp-traces-endpoint parameter exec vllm serve <model-name> \ --served-model-name <model-name> \ --trust-remote-code \ --otlp-traces-endpoint http://eagle-eye-tracing-collector.<release-namespace>.svc.cluster.local:4317 \ --port 8000 # Other parameters... # Add environment variables env: - name: OTEL_SERVICE_NAME valueFrom: fieldRef: fieldPath: metadata.name - name: VLLM_ASCEND_TRACING_ENABLED value: "1" - name: VLLM_ASCEND_TRACING_LOG_LEVEL value: "INFO" # Add volume mounts volumeMounts: - name: tracing-install mountPath: /tracing-install readOnly: true # Add volume definition volumes: - name: tracing-install emptyDir: {}Note: Placeholders such as
<your-vllm-ascend-image>:<tag>,<model-name>,<release-namespace>in the configuration need to be replaced with actual values.Configuration Description:
Table 3 vLLM-Ascend Tracing Configuration Description
Configuration Item Description initContainers.install-tracingCopies files from tracing image to shared volume. --otlp-traces-endpointOTLP receiving address of Jaeger Collector. OTEL_SERVICE_NAMEOpenTelemetry service name, uses Pod name. VLLM_ASCEND_TRACING_ENABLEDEnable vLLM-Ascend tracing. VLLM_ASCEND_TRACING_LOG_LEVELTracing log level. /tracing-install/install.shInstalls tracing module to Python site-packages. Apply configuration.
bashkubectl apply -f vllm-ascend-deployment.yamlWait for the Pod to start, check Pod running status:
bashkubectl get pods -n ai-inference | grep vllm-ascendConfirm Pod status is
Runningand all initContainers have completed successfully.
Querying Jaeger UI
Confirm tracing-related Pods are running normally.
bashkubectl get pods -n <release-namespace> | grep eagle-eye-tracingConfirm all related Pod statuses are
Running.Send inference requests.
bashcurl -X POST http://<vllm-service-address>:8000/v1/completions \ -H "Content-Type: application/json" \ -d '{ "model": "<model-name>", "prompt": "Hello, how are you?", "max_tokens": 50 }'Replace
<vllm-service-address>with the actual vLLM service address.Get the Jaeger UI access address.
bashkubectl get svc -n <release-namespace> | grep eagle-eye-tracing-queryRecord the NodePort port number (e.g.,
30686) and node IP address from the output.Access Jaeger UI.
Access
http://<node-ip>:<node-port>(e.g.,http://192.168.1.100:30686) in the browser to enter the Jaeger UI.View Trace data.
Select
vllm-ascendfrom the Service drop-down list in the Jaeger UI, click the Find Traces button, and confirm that the Trace list is visible.View Trace details.
Click a Trace to expand and view detailed information, confirming that you can see Spans for each stage:
vllm_ascend.request: Full request lifecycle.vllm_ascend.prefill_execution: Prefill phase.vllm_ascend.decode_phase: Decode phase.- And sub-Spans for each stage (scheduling, KVCache allocation, etc.).
Licensed under the MulanPSL2
 YueGongWangAnBei No.44030002007300