ResourceScalingGroup - Resource Group Scaling
Feature Introduction
ResourceScalingGroup (hereinafter referred to as RSG) is a controller for Kubernetes workload group scaling scenarios. It abstracts multiple related workloads into a logical group, uniformly describes scaling strategies with a custom resource, and is responsible for implementing the strategies on specific resources. The current implementation provides two scaling strategies:
GroupReplication: Using a group of basic workloads as templates, replicating, recovering, and scaling down by "group", suitable for scenarios that require cloning a complete inference chain or group scaling in Prefill-Decode separated architectures.InplaceScaling: Using the leader resource's replicas value as a baseline, scaling follower resources' replica count proportionally, suitable for Prefill-Decode separated architectures where Prefill-Decode groups scale collaboratively at a fixed ratio.
RSG directly targets the resource orchestration layer and does not handle complex business metric comprehensive decision-making. For GroupReplication scenarios, it exposes a standard scale sub-resource and can serve as a target object for upper-layer policies such as HPA, ElasticScaler, and TidalScheduler. The upper-layer policies decide "how many groups to scale to", and then RSG executes the in-group resource orchestration.
Application Scenarios
- Multiple components such as prefill, decode, and gateway in large model inference chains need to scale as groups.
- A business unit contains multiple Deployments, StatefulSets, or LeaderWorkerSets, and it's desired to replicate them as multiple independent instances at once.
- Business replica counts have a certain proportional relationship, i.e., when the leader resource's replica count changes, follower resources need to adjust synchronously at a fixed ratio.
- Need to manage existing business in the cluster, giving deployed resources scaling capabilities.
- When business needs to scale down to release computing resources, graceful scaling can be performed based on business metrics to minimize impact on business.
Capability Scope
- Manage a group of target resources based on the standard CRD ResourceScalingGroup, with at least 1 target resource.
- Support managing Deployment, StatefulSet, and LeaderWorkerSet workloads.
- Support
GroupReplicationgroup scaling strategy, scaling up and down by "resource group", automatically managing workload cloning and associated Service cloning. - Support
InplaceScalingin-place scaling strategy, calculatingfollowerreplicas byleader.replicas * followRatio. - Support integrating Prometheus metrics during group scale-down, selecting priority groups to reclaim by metric values.
- Support degrading to annotation values when Prometheus is unavailable or metrics are incomplete, then further degrading to maximum group-id scale-down selection logic.
- In
GroupReplicationstrategy, exposescalesub-resource, allowing upper-layer controllers such as HPA to drive group count changes through standard scaling interfaces. - Validate common configuration issues through Webhook such as duplicate targets, illegal references, role configuration errors, and leader/follower relationship errors.
Highlight Features
- Treat "resource groups" as scaling objects: Upper decision systems don't need to operate multiple Deployment or StatefulSet resources separately, only need to target one RSG resource.
- Cover two typical orchestration modes simultaneously: Support both whole group resource scaling and Pod count linkage according to leader/follower ratio, with broader coverage than simple replica scaling.
- Support decoupled combination with upper-layer policies: GroupReplication exposes scale sub-resource, can be connected to HPA, ElasticScaler, TidalScheduler and other external policies.
- Clear observability and degradation mechanism for scale-down process: Prioritize scale-down by Prometheus metrics, automatically degrade on failure, avoiding scale-down failure due to single-point metric issues.
Implementation Principle
This section explains the implementation principle of ResourceScalingGroup from deployment view, runtime view, and schematic diagrams of two scaling strategies.
Deployment View
Figure 1 RSG Deployment View
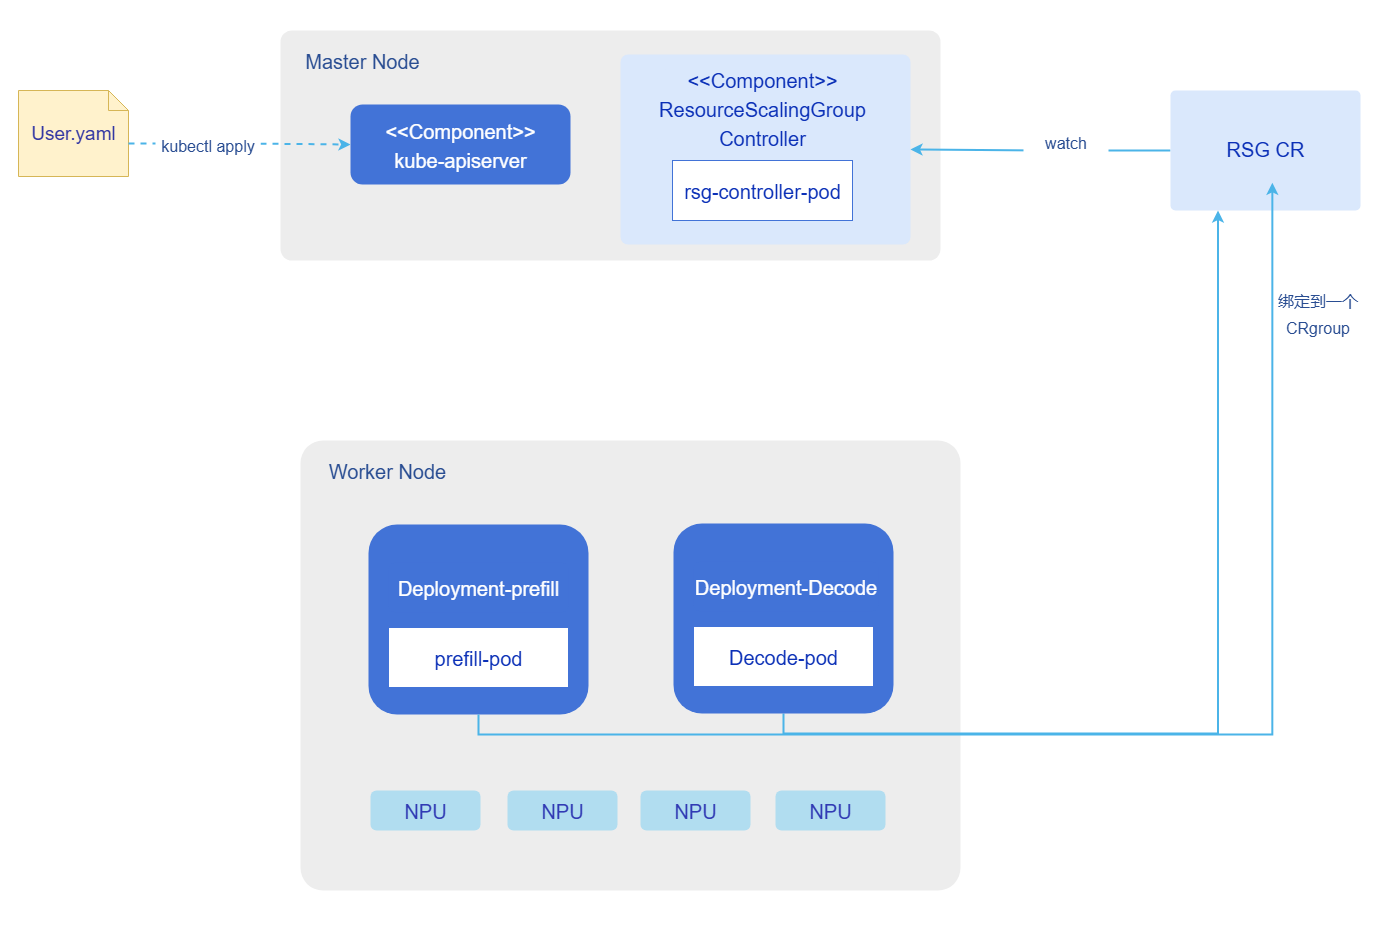
From the component deployment perspective, the RSG controller is deployed as a deployment. Through an RSG CR resource, Prefill and Decode resources are bound into a group. When scaling up, it scales at group granularity, creating new Deployment-Prefill and Deployment-Decode resource replicas, as shown in the GroupReplication group scaling strategy diagram below:
Figure 2 Scaling Schematic Diagram Under GroupReplication Strategy
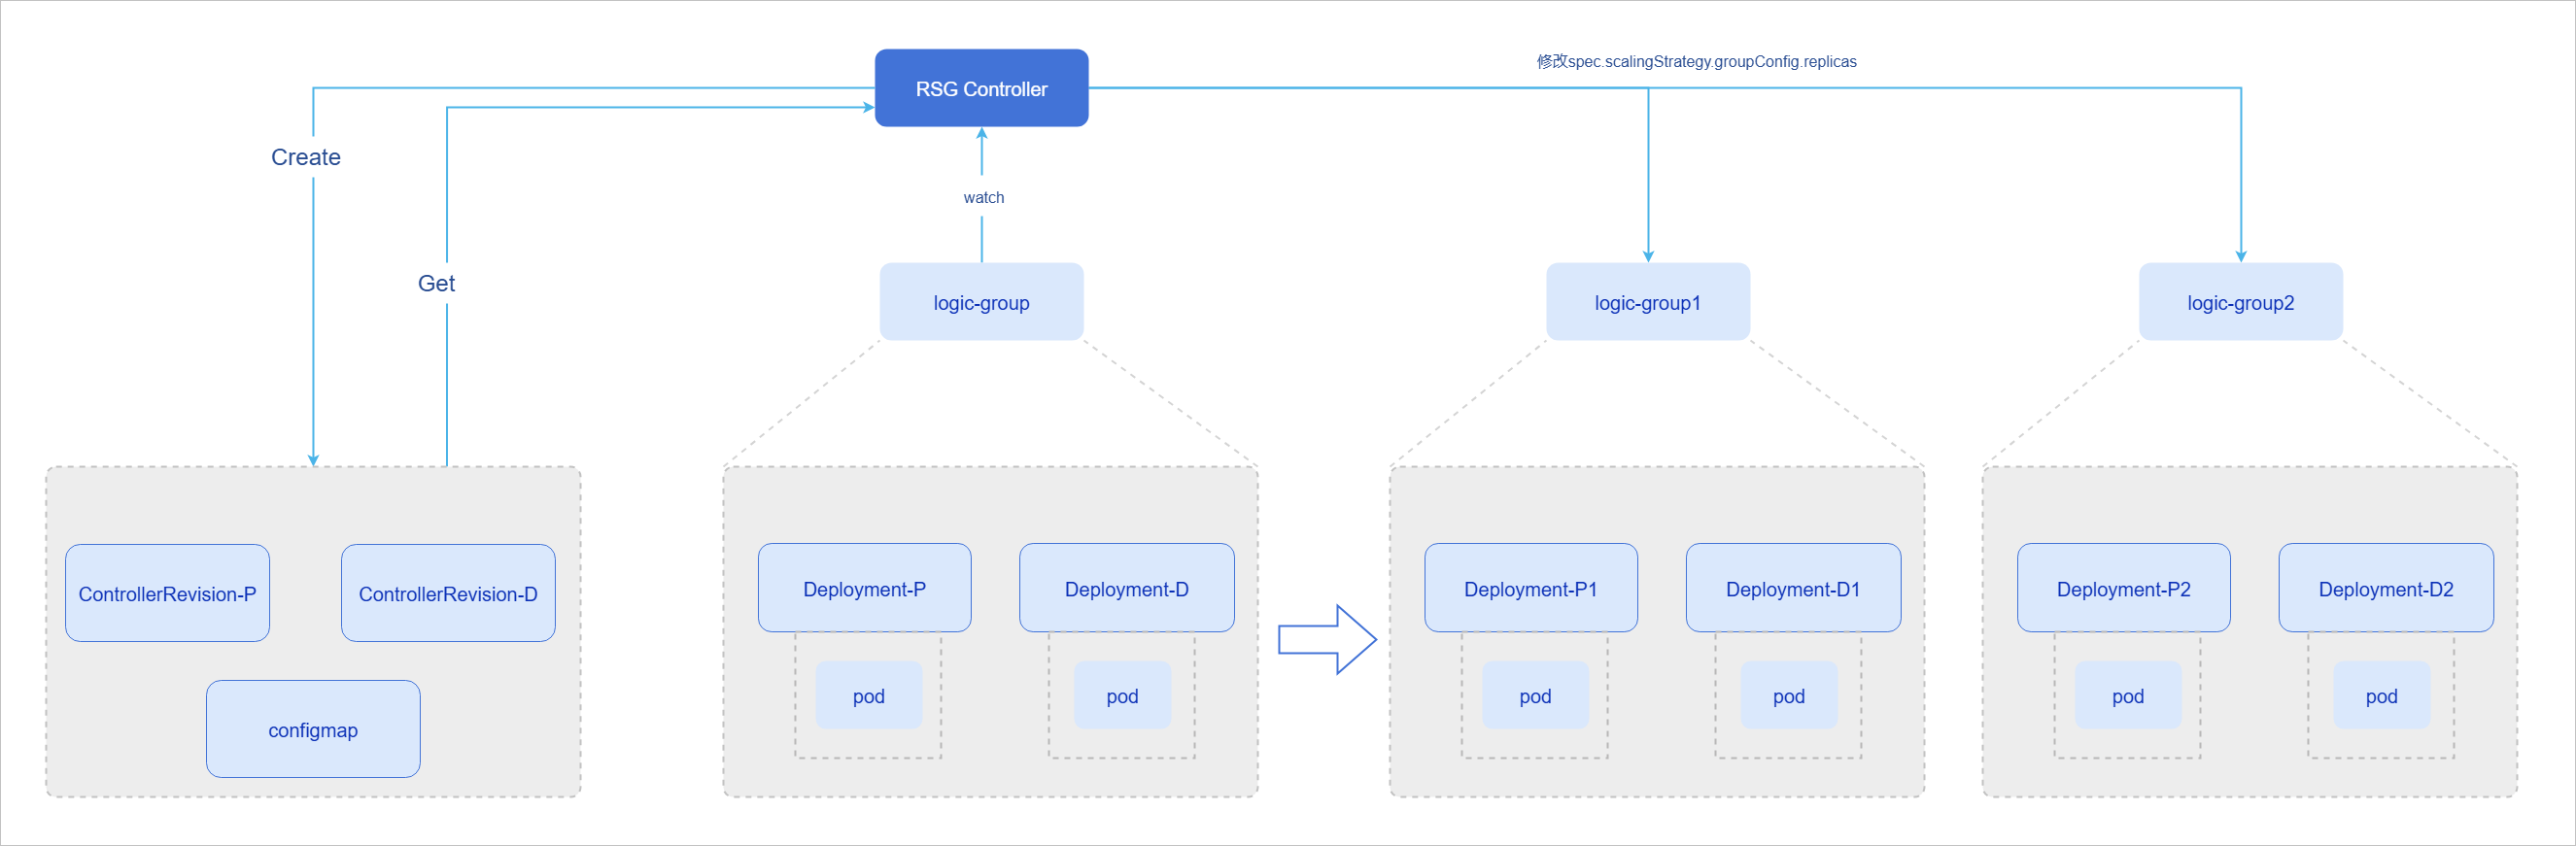
After the controller takes over Prefill and Decode resources, it creates corresponding ControllerRevision snapshots and ConfigMaps that can dynamically modify Pod counts. When scaling up, resource replicas are created based on snapshot configuration information. At this time, the Pod count of new resources should remain consistent with the original resources. If you need to dynamically modify the Pod count ratio of new resource replicas, you can modify the ConfigMap file configuration. For details, refer to Related Operations.
Note
In the current version, RSG creates replica resources based on snapshots. If the original resource group configuration is updated, the snapshot will not be updated, and resources will still be created based on the old snapshot when scaling up. If you need new resource replicas configured according to the updated original resource group, you can delete the old ControllerRevision and ConfigMap resources before scaling up.
The InplaceScaling in-place scaling strategy diagram is as follows:
Figure 3 InplaceScaling In-place Scaling Strategy Diagram
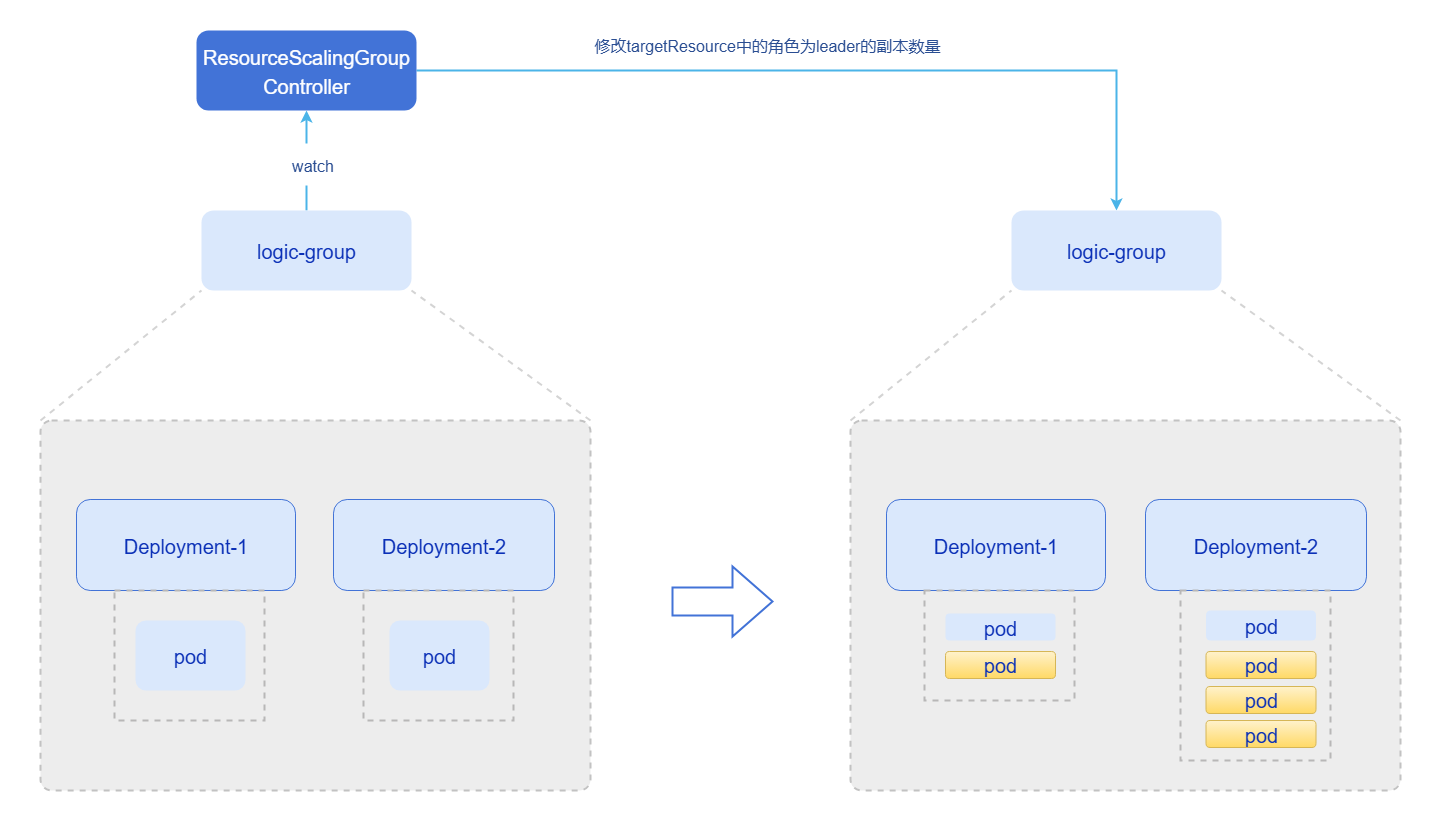
In this mode, the Pod count of Deployment resources is scaled. If Deployment-1 is the leader object and Deployment-2 is the follower object, modifying the replicas value of Deployment-1, the follower replicas value can be calculated through leader.replicas * followRatio, achieving the purpose of linkage scaling.
Runtime View
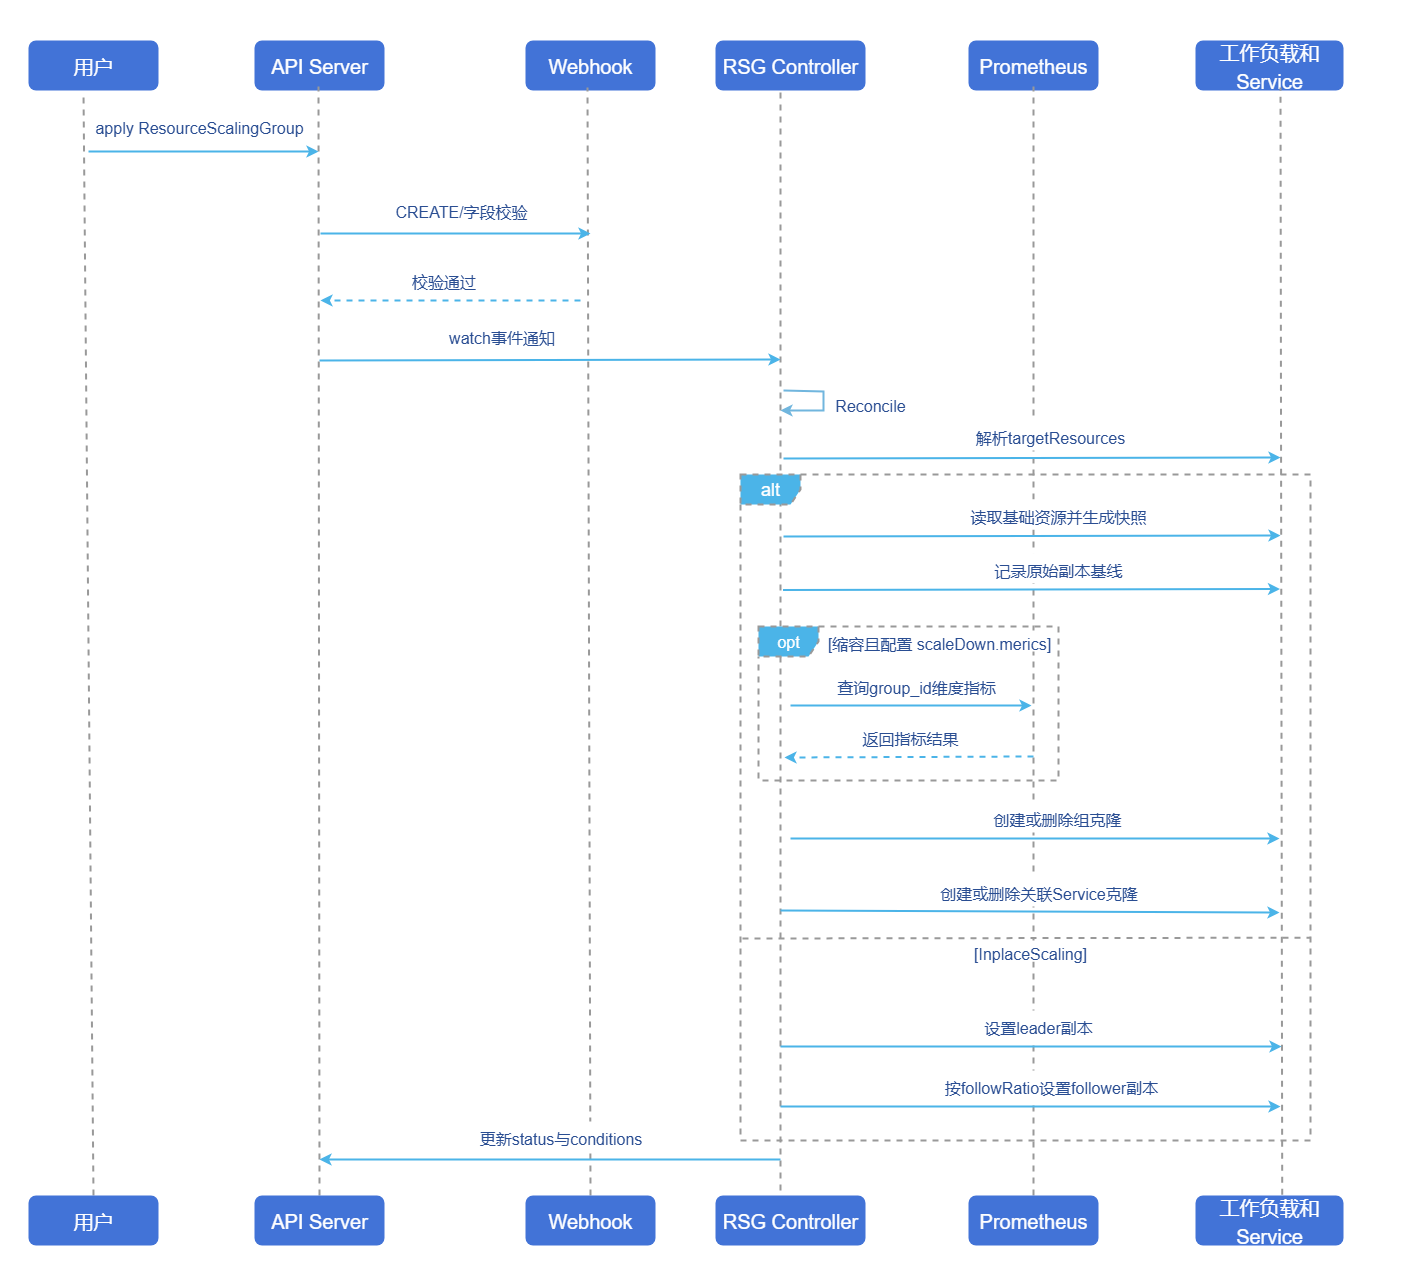
The typical running process of RSG is divided into four phases:
- Users submit ResourceScalingGroup CR resources, and Webhook validates target resources, strategy types, role configurations, and cross-group conflicts.
- Controller selects strategy engine based on
scalingStrategy.typeand parses the actual workload of eachtargetResources. - If it's
GroupReplication, Controller generates snapshots for basic resources, records original replica baselines, fills in group labels and Services, then creates or reduces according to target group count; if it'sInplaceScaling, directly adjusts the replicas ofleaderandfollowerto target values. - Controller writes back
status, upper-layer policies or operation systems can continue to observe, audit and linkage based on status.
Figure 4 RSG Controller Runtime View
Relationship with Related Features
ElasticScaler: RSG is one of the typical scaling targets of ElasticScaler. ElasticScaler can point targetRef to ResourceScalingGroup to manage RSG replica scaling.
TidalScheduler: TidalScheduler can use RSG as a tidal scheduling target, directly adjusting RSG replica count at specified time points.
HPA: Since RSG exposes standard scale sub-resource for GroupReplication, HPA resources can directly scale RSG resources.
Prometheus: Prometheus is not a hard dependency of RSG, but if scaleDown.metric is configured, RSG will prioritize calling Prometheus to query metrics with group_id dimension to decide which groups to reclaim first during scale-down.
Installation
Standalone Deployment
This section introduces how to independently deploy ResourceScalingGroup in a k8s cluster with existing inference services.
Prerequisites
Before starting installation, please ensure the following conditions are met:
- Environment Requirements:
- Kubernetes cluster: v1.28.0 and above.
- Cluster administrator privileges: for installing CRD and cluster resources.
- Helm tool: for deploying ResourceScalingGroup and related components.
- Hardware Requirements:
- No special hardware requirements.
Installing ResourceScalingGroup
Execute the following command to install ResourceScalingGroup.
helm install rsg oci://cr.openfuyao.cn/charts/pd-orchestrator --version 0.0.0-latest \
--set resourcescalinggroup.namespace.create=true # Default is false, if the cluster does not contain the scaling-system namespace, this needs to be set to true.
Install pd-orchestrator chart from OCI repository. This chart will install ElasticScaler, RSG and Tidal three components by default, and create one RSG CR and ElasticScaler CR instance configuration by default.
If you currently only need to deploy RSG Controller, it is recommended to explicitly disable other components and default sample instances:
helm install pd-orchestrator oci://cr.openfuyao.cn/charts/pd-orchestrator --version 0.0.0-latest \
  --set elastic-scaler.enabled=false \
  --set resourcescalinggroup.enabled=true \
  --set resourcescalinggroup.instanceConfig.enabled=false \
  --set tidal.enabled=false \
  --set resourcescalinggroup.namespace.create=true # Default is false, if the cluster does not contain the scaling-system namespace, this needs to be set to true.
Key Parameter Description
Table 1 Helm Package Installation Parameter Description
| Parameter Key | Description |
|---|---|
resourcescalinggroup.enabled | Controls whether to deploy RSG Controller in the orchestrator chart. |
resourcescalinggroup.instanceConfig.enabled | Controls whether to create default RSG sample CR. It is recommended to explicitly set to false in production environment. |
resourcescalinggroup.namespace.name | The namespace where RSG Controller is deployed, default is scaling-system. |
resourcescalinggroup.namespace.create | Does not create scaling-system namespace by default. If the cluster does not contain scaling-system namespace, this needs to be set to true. |
resourcescalinggroup.prometheus.url | Prometheus query address, used by scaleDown.metric, will be injected into environment variable RSG_PROMETHEUS_URL. |
resourcescalinggroup.webhook.enabled | Controls whether to enable RSG's mutating/validating webhook. |
resourcescalinggroup.webhook.failurePolicy | Webhook failure policy, default is Ignore in chart. Can be adjusted according to risk preference for production environment. |
resourcescalinggroup.replicaCount | RSG Controller Pod replica count. |
elastic-scaler.enabled | Whether to deploy ElasticScaler at the same time, used to make RSG as upper-layer scaling target. |
tidal.enabled | Whether to deploy TidalScheduler at the same time, used to adjust RSG group count by time. |
When
resourcescalinggroup.instanceConfig.enabled=true, the chart will automatically create a defaultResourceScalingGroupinstance. It is usually not recommended to keep this default sample in production environment to avoid it mistakenly operating existing business resources.
InferNex Integrated Deployment
InferNex is a one-click integrated intelligent routing, monitoring and elastic scaling deployment suite, which internally includes the RSG component.
Prerequisites
- Kubernetes v1.28.0 and above.
- At least one inference chip per inference node.
- At least 16GB memory and 4 CPU cores per inference node.
- Online installation can access image repository: oci://cr.openfuyao.cn.
- User has permission to create RBAC resources.
Quick Installation of InferNex
InferNex has the following two ways for independent deployment:
Obtain project installation package from openFuyao official artifact repository.
Install from remote repository.
bashhelm install infernex oci://cr.openfuyao.cn/charts/infernex --version xxxWhere
xxxneeds to be replaced with the specific project installation package version, such as0.21.1,infernexis the release name.Before executing installation, please ensure:
- The cluster has created namespaces
istio-system(Istio Gateway resources must be deployed in this namespace) andscaling-system.
- The cluster has created namespaces
Obtain from openFuyao GitCode repository.
Pull project from repository.
bashgit clone https://gitcode.com/openFuyao/InferNex.gitInstall and deploy.
Taking release name
infernexas an example, execute the following command in the same directory asInferNex:bashcd InferNex/charts/infernex helm dependency build helm install -n <namespace> infernex .
Verify Deployment
After completing installation, you can verify whether RSG Controller is running normally through the following steps.
Check Pod status.
bashkubectl get Pods -n scaling-system | grep -E "resourcescalinggroup|rsg"Check if CRD is installed successfully.
bashkubectl get crd resourcescalinggroups.autoscaling.openfuyao.comCheck Controller logs.
bashkubectl get deploy -n scaling-system kubectl logs -n scaling-system deploy/<deployment-name>If Webhook is enabled, confirm related configuration objects exist.
bashkubectl get validatingwebhookconfigurations | grep resourcescalinggroup
If deployment is abnormal, prioritize checking the following items.
- Whether the namespace is correct and whether the image is successfully pulled.
- Whether Prometheus URL is reachable.
- Whether Webhook certificate, caBundle or cert-manager configuration is correct.
- Whether there is a default sample CR mistakenly operating existing business resources.
Using ResourceScalingGroup
Prerequisites
- ResourceScalingGroup deployment has been completed according to Installation steps, and RSG Controller is running normally.
- Target workloads to be managed already exist in the cluster, and the names and namespaces of target workloads have been confirmed.
- If using the scale-down by metric capability of
GroupReplication, Prometheus must have metrics withgroup_idlabel. - If planning to let ElasticScaler, TidalScheduler or HPA drive RSG, please confirm the current RSG type is
GroupReplication.
Background Information
RSG's
spec.targetResourcesdefines a group of managed workloads, each target usesnameas a logical reference name for strategy configuration reference.GroupReplicationusesspec.scalingStrategy.groupConfig.replicasto represent the desired group count. This value is also mapped to thescalesub-resource in CRD, so upper-layer controllers can directly treat RSG as a scalable object.InplaceScalingusesleaderFollowerConfigto defineleaderandfollowerrelationship, where the target replica count offolloweris calculated asleader.replicas * followRatio.For
GroupReplication, RSG will generateControllerRevisionsnapshots for basic resources and use aConfigMapnamed<rsg-name>-replica-configto save the original replica baseline of each target resource, used for recovery from 0 groups or creating new groups.If
scaleDown.metricis configured, RSG will construct PromQL similar to:textavg by (group_id) (demo_metric) sum by (group_id) (rate(demo_counter[window]))Note- Default aggregator for Gauge is
avg. - Counter and Histogram need to configure
windowfield, default aggregator issum. - When
metric.type=Gauge, the calculation logic is<aggregator> by (group_id) (<expr>), i.e., directly aggregate current values bygroup_idgrouping. - When
metric.type=Counterormetric.type=Histogram, the calculation logic is<aggregator> by (group_id) (rate(<expr>[<window>])), i.e., first do growth rate within window, then aggregate bygroup_id.
- Default aggregator for Gauge is
Usage Limitations
scalesub-resource only makes sense forGroupReplication.- New group resource names created by
GroupReplicationfollow<groupName>-<original resource name>-<groupID>, associated Service names follow<original Service name>-<groupName>-<groupID>. The controller will not automatically avoid naming conflicts; if a resource with the same name already exists in the cluster, creation will fail. - New resources generated by group replication will be created in RSG's namespace. If the basic target resources are in other namespaces, the impact of cross-namespace template replication needs to be evaluated in advance.
- Under the same strategy type, multiple RSGs are not allowed to reference the same target workload simultaneously. Webhook will validate duplicate references, but operation side is still advised to follow the principle of "one target managed by one RSG".
- When the target group count of
GroupReplicationdrops to 0, the controller will scale the basic resources ofgroup 0to 0 replicas, rather than deleting the basic resource objects. - When deleting a
GroupReplicationtype RSG, the controller defaults to preserving existing business resource instances, only cleaning up control plane artifacts such as snapshots and configurations; deleting RSG CR does not equal deleting generated group resources. If you want to thoroughly clean up business resources, users need to manually reclaim them as needed. - The scale-down selection phase will sort based on the final value of each
group_idmentioned above, executing sorting according toscaleDown.order:ascendingprioritizes reclaiming smaller values,descendingprioritizes reclaiming larger values. - Type enumerations are
Counter,Gauge,Histogram. If written asguageit will be treated as an illegal value. - To make
scaleDown.metrictruly effective, the data returned by Prometheus must include thegroup_idlabel, and the label value must correspond to the group number created by RSG; if this label is missing, RSG will automatically fall back to degradation logic instead of scaling down by metric values. For details, refer to Related Operations. - When users use
GroupReplication, even if original target resources are in other namespaces, new group resources and their cloned Services will still be created in the namespace where RSG CR is located.
Operation Steps
Using GroupReplication to Manage a Group of Prefill-Decode Instances
The following example combines two Deployments, prefill and decode, into a resource group with an initial group count of 2 and configures scale-down priority based on Prometheus metrics:
yamlapiVersion: autoscaling.openfuyao.com/v1alpha1 kind: ResourceScalingGroup metadata: name: llm-Prefill-Decode-group namespace: scaling-system spec: targetResources: - name: prefill resourceRef: apiVersion: apps/v1 kind: Deployment name: llm-prefill namespace: production - name: decode resourceRef: apiVersion: apps/v1 kind: Deployment name: llm-decode namespace: production scalingStrategy: type: GroupReplication groupConfig: groupName: Prefill-Decode replicas: 2 scaleDown: metric: expr: "vllm:num_requests_running" type: Gauge aggregator: avg order: ascendingCommon field descriptions are as follows:
Table 2 RSG CR Field Description
Field Path Required Description metadata.nameYes RSG resource name, unique within namespace. metadata.namespaceYes RSG's namespace, also the default namespace for creating new group resources. spec.targetResources[].nameYes Target resource logical name, used for strategy configuration reference, must be unique within the group. spec.targetResources[].resourceRef.apiVersionYes Target workload's API version. spec.targetResources[].resourceRef.kindYes Target workload type, such as Deployment, StatefulSet, LeaderWorkerSet, RoleBasedGroup. spec.targetResources[].resourceRef.nameYes Target workload name. spec.targetResources[].resourceRef.namespaceNo Target workload namespace. Defaults to RSG's namespace when empty. spec.scalingStrategy.typeYes Strategy type, value is GroupReplication or InplaceScaling. spec.scalingStrategy.groupConfig.groupNameNo Group name prefix. Defaults to RSG name when empty. spec.scalingStrategy.groupConfig.replicasYes Desired group count. For GroupReplication, also the target value of scale sub-resource. spec.scalingStrategy.groupConfig.scaleDown.metric.exprNo Scale-down reference metric expression or metric name. spec.scalingStrategy.groupConfig.scaleDown.metric.typeNo Metric type: Counter, Gauge, Histogram. spec.scalingStrategy.groupConfig.scaleDown.metric.windowConditionally Required Required when metric type is Counter or Histogram. spec.scalingStrategy.groupConfig.scaleDown.metric.aggregatorNo Aggregator: sum, avg, max, min. spec.scalingStrategy.groupConfig.scaleDown.orderNo Scale-down sort direction: ascending or descending. Create resource.
bashkubectl apply -f llm-Prefill-Decode-group.yamlCheck status.
bashkubectl get resourcescalinggroup llm-Prefill-Decode-group -n scaling-system -o yamlFocus on the following status fields:
status.currentReplicas: Currently observed group count.status.lastDesiredReplicas: Last desired target group count by controller.status.selector: Label selector used byscalesub-resource.status.conditions:Ready=True,Reason=Reconciledindicates last reconciliation succeeded.
Check resources created by this group.
bashkubectl get deploy -n scaling-system | grep "-Prefill-Decode-"If you need to manually adjust the group count, you can directly modify RSG.
bashkubectl patch resourcescalinggroup llm-Prefill-Decode-group -n scaling-system \ --type merge \ -p '{"spec":{"scalingStrategy":{"groupConfig":{"replicas":3}}}}'If you need upper-layer policies to drive the group count, you can point ElasticScaler, TidalScheduler or HPA to this RSG instead of directly pointing to in-group Deployments.
Using InplaceScaling to Manage leader / follower Linkage Replicas
The following example uses scheduler as leader, worker and sidecar as followers. Leader is fixed at 3 replicas, worker follows at 2x, sidecar follows at 1x:
apiVersion: autoscaling.openfuyao.com/v1alpha1
kind: ResourceScalingGroup
metadata:
  name: leader-follower-rsg
  namespace: scaling-system
spec:
  targetResources:
    - name: scheduler
      resourceRef:
        apiVersion: apps/v1
        kind: Deployment
        name: scheduler
        namespace: production
    - name: worker
      resourceRef:
        apiVersion: apps/v1
        kind: Deployment
        name: worker
        namespace: production
    - name: sidecar
      resourceRef:
        apiVersion: apps/v1
        kind: Deployment
        name: sidecar
        namespace: production
  scalingStrategy:
    type: InplaceScaling
    leaderFollowerConfig:
      leader:
        resourceName: scheduler
        replicas: 3
      follower:
        - resourceName: worker
          followRatio: 2
        - resourceName: sidecar
          followRatio: 1
Field descriptions are as follows:
Table 3 leaderFollowerConfig Field Description
| Field Path | Required | Description |
|---|---|---|
spec.scalingStrategy.leaderFollowerConfig.leader.resourceName | Yes | Corresponding targetResources[].name for leader. |
spec.scalingStrategy.leaderFollowerConfig.leader.replicas | Yes | Target replica count for leader. |
spec.scalingStrategy.leaderFollowerConfig.follower[].resourceName | Yes | Corresponding targetResources[].name for follower. |
spec.scalingStrategy.leaderFollowerConfig.follower[].followRatio | Yes | Follower's replica ratio relative to leader, minimum value is 1. |
Create resource.
kubectl apply -f leader-follower-rsg.yamlCheck RSG status.
kubectl describe resourcescalinggroup leader-follower-rsg -n scaling-systemCheck target resource replicas.
kubectl get deploy scheduler worker sidecar -n productionIn the above example, expected replica relationships are:
- scheduler = 3
- worker = 6
- sidecar = 3
Follow-up Operations
- Regularly adjust
groupConfig.replicas,scaleDown.metricorleaderFollowerConfigaccording to business scale changes. - If you need to connect RSG to upper-layer policies, prioritize letting upper-layer systems target RSG to adjust groups instead of directly changing in-group resources.
- If you need to disable an RSG, you can first adjust the group count to the desired value, then evaluate whether to delete CR; for GroupReplication, before deletion, clarify whether to keep generated business resources.
Delete resource example.
kubectl delete resourcescalinggroup llm-Prefill-Decode-group -n scaling-systemRelated Operations
View all RSG instances.
bashkubectl get resourcescalinggroup -AView single instance details.
bashkubectl describe resourcescalinggroup llm-Prefill-Decode-group -n scaling-systemView scale sub-resource.
bashkubectl get --raw "/apis/autoscaling.openfuyao.com/v1alpha1/namespaces/scaling-system/resourcescalinggroups/llm-Prefill-Decode-group/scale"View replica baseline ConfigMap recorded by controller.
bashkubectl get configmap llm-Prefill-Decode-group-replica-config -n scaling-system -o yamlView basic resource snapshots.
bashkubectl get controllerrevision -n scaling-system | grep "llm-Prefill-Decode-group"Scale down sorted by annotation value
If prometheus metrics cannot be collected, or some groups have missing metrics, it will fall back to using annotation values for sorted scale-down. If users need to use annotation value sorted scale-down, they need to inject annotations like
autoscaling.rsg.metric.values: "10"into theannotationsofspec.targetResources[0]resource. RSG Controller will perform ascending or descending scale-down based on the values size andscaleDown.orderpolicy. If annotation value is missing, it will fall back to scale-down bygroup-idfrom large to small. An example is given below.yamlapiVersion: autoscaling.openfuyao.com/v1alpha1 kind: ResourceScalingGroup metadata: name: llm-Prefill-Decode-group namespace: scaling-system spec: targetResources: - name: prefill resourceRef: apiVersion: apps/v1 kind: Deployment name: llm-prefill - name: decode resourceRef: apiVersion: apps/v1 kind: Deployment name: llm-decode scalingStrategy: type: GroupReplication groupConfig: groupName: Prefill-Decode replicas: 1 scaleDown: metric: expr: "vllm:num_requests_running" type: Gauge aggregator: avg order: ascendingIf users need to scale down according to annotation values, they need to inject annotations like
autoscaling.rsg.metric.values: <specific values>into theannotationsfield ofllm-prefillDeployment and its replica Deployments. As shown below.yaml# llm-prefill Deployment metadata: annotations: autoscaling.rsg.metric.values: 10 name: llm-prefill --- # llm-prefill-1 Deployment metadata: annotations: autoscaling.rsg.metric.values: 5 name: llm-prefill-1 --- # llm-prefill-2 Deployment metadata: annotations: autoscaling.rsg.metric.values: 1 name: llm-prefill-2At this time, RSG Controller will scale down in the order of
[llm-prefill-2, llm-prefill-1, llm-prefill].
Modify Pod count of new resource replicas
When you need to modify the Pod count of resource replicas after scaling up, you can modify the
<rsg-name>-replica-configConfigMap resource, as shown below.yamlapiVersion: v1 kind: ConfigMap metadata: name: rsg-demo-replica-config namespace: default labels: rsg.io/name: rsg-demo data: prefill: "1" decode: "1"At this time, the Pod count of new replica Deployment-Prefill and Deployment-Decode are both 1. If modified to:
yamlapiVersion: v1 kind: ConfigMap metadata: name: rsg-demo-replica-config namespace: default labels: rsg.io/name: rsg-demo data: prefill: "2" decode: "2"At this time, the Pod count of new replica Deployment-Prefill and Deployment-Decode are both 2.
Prepare Service and ServiceMonitor for
scaleDown.metricIf you want RSG to prioritize reclaim groups by business metrics during scale-down, you need to first ensure the target metrics have been collected normally by Prometheus. For clusters using Prometheus Operator, at least the following are usually required:
- The application itself exposes Prometheus format metrics on a certain port.
- Application metrics include
group_idlabel, and the value is consistent with RSG group number, for example 0, 1, 2. - Create Service for this metric endpoint.
- Create ServiceMonitor for this Service.
A complete example is given below. Assume:
- Business is deployed in ai-inference namespace.
- Each in-group Pod exposes :8000/metrics.
- Metric name is
vllm:num_requests_runningwithgroup_idlabel.
Service exposed by application.
yamlapiVersion: v1 kind: Service metadata: name: vllm-metrics namespace: ai-inference labels: app: vllm-metrics spec: selector: openfuyao.com/model: qwen-qwen3-8b openfuyao.com/engine: vllm ports: - name: metrics port: 8000 targetPort: 8000 type: ClusterIPServiceMonitor used by Prometheus Operator.
yamlapiVersion: monitoring.coreos.com/v1 kind: ServiceMonitor metadata: name: vllm-metrics namespace: monitoring labels: release: kube-prometheus-stack spec: namespaceSelector: matchNames: ["ai-inference"] selector: matchLabels: app: vllm-metrics endpoints: - port: metrics path: /metrics interval: 5s scrapeTimeout: 4s relabelings: - action: drop regex: ^vllm-metrics;([1-9][0-9]*)$ sourceLabels: [__meta_kubernetes_service_name;__meta_kubernetes_Pod_label_rsg_io_group_id] - action: replace sourceLabels: [__meta_kubernetes_Pod_label_group_id] regex: (.+) targetLabel: group_id - action: replace sourceLabels: [__meta_kubernetes_Pod_label_rsg_io_group_id] regex: (.+) targetLabel: group_id - action: replace sourceLabels: [group_id] regex: ^$ targetLabel: group_id replacement: "0"Metric output format reference is as follows.
text# HELP vllm_num_requests_running Current running requests for a replica group # TYPE vllm_num_requests_running gauge vllm:num_requests_running{group_id="0"} 3 vllm:num_requests_running{group_id="1"} 11 vllm:num_requests_running{group_id="2"} 5In the above example, RSG can be configured as follows.
yamlscaleDown: metric: expr: "vllm:num_requests_running" type: Gauge aggregator: avg order: ascendingNote- ServiceMonitor depends on monitoring.coreos.com/v1 CRD; if the cluster has not installed Prometheus Operator, need to use the cluster's existing Prometheus scrape configuration method.
- Pods selected by
Service.spec.selectormust cover all groups participating in scale-down decision, otherwise metrics will be incomplete. - If some groups do not return
group_idmetrics, RSG will not forcibly make decisions based on incomplete data, but will fall back to annotation orgroup-idfallback logic. - To avoid confusion between metric names and PromQL expressions, it is recommended to first verify in Prometheus UI that
avg by (group_id) (vllm_num_requests_running)can return results normally before writing to RSG.
FAQ
The following lists the most common failure phenomena, possible causes and recommended inspection items when users use RSG.
1. RSG created, but no new group resources generated
Symptom description: RSG resource created to cluster, but bound resource group has not created new resource replicas.
Possible causes:
spec.scalingStrategy.groupConfig.replicasactual value is not greater than current group count.- Target resource does not exist, or
apiVersion,kind,name,namespacefilled incorrectly. - New group resource name conflicts with existing resources in cluster.
- Controller does not have access or create permission for target resources.
Recommended inspection:
kubectl get resourcescalinggroup llm-Prefill-Decode-group -n scaling-system -o yaml
kubectl describe resourcescalinggroup llm-Prefill-Decode-group -n scaling-system
kubectl logs -n scaling-system deploy/<rsg-controller-deployment>
Focus on confirming:
- Whether
Ready=Falseor error reason appears instatus.conditions. - Whether there are keywords like target resource not found, already exists, forbidden in logs.
- Whether target resources really exist:
kubectl get deploy llm-prefill -n production
kubectl get deploy llm-decode -n production
2. RSG created group resources, but group count inconsistent with expectation
Symptom description: RSG field replicas value inconsistent with actual replicas count.
Possible causes:
- Still in reconciliation convergence process, Controller is still filling missing groups or cleaning up excess groups.
- Some group resources created successfully, others failed due to naming conflicts or permission issues.
- group 0 was previously scaled to 0, currently in recovery and secondary reconciliation phase.
Recommended inspection:
kubectl get resourcescalinggroup llm-Prefill-Decode-group -n scaling-system -o yaml
kubectl get deploy -n scaling-system
kubectl get svc -n scaling-system
kubectl logs -n scaling-system deploy/<rsg-controller-deployment>
Focus on confirming:
- Whether
status.currentReplicasandstatus.lastDesiredReplicasare continuously inconsistent. - Whether logs repeatedly show requeue for convergence.
- Whether some group resources only partially created, for example workload created but corresponding Service not created successfully.
3. scaleDown.metric configured, but scale-down not executed by metric
Symptom description: Scale-down not sorted by metric.
Possible causes:
- resourcescalinggroup.prometheus.url not configured or Prometheus not accessible.
- expr, type, window, aggregator configured incorrectly.
- Data returned by Prometheus does not have
group_idlabel, orgroup_idvalue does not match actual group number. - Some candidate groups do not return metrics, RSG automatically falls back to degradation logic.
Recommended inspection:
kubectl logs -n scaling-system deploy/<rsg-controller-deployment> | grep -i prometheus
kubectl logs -n scaling-system deploy/<rsg-controller-deployment> | grep -i group_id
Verify query result in Prometheus UI or API:
avg by (group_id) (vllm_num_requests_running)Focus on confirming:
- Whether metric values for all candidate groups can be queried.
- Whether returned results are like
{group_id="0"},{group_id="1"}, and all groups have metric collection. - If it's Counter or Histogram, whether window is configured.
- If logs show fallback to annotation or fallback to max group-id, it means current decision was not completed based on Prometheus metrics.
4. ServiceMonitor created, but business metrics cannot be queried in Prometheus
Symptom description: Viewing prometheus URL, reported metric labels have no group id field or no business metrics.
Possible causes:
- Cluster has not installed Prometheus Operator, ServiceMonitor not consumed.
- ServiceMonitor.metadata.labels do not meet selector requirements of Prometheus instance.
Service.spec.selectordoes not select Pods that actually expose metrics.- Pod actually has not opened metrics port or /metrics path.
Recommended inspection:
kubectl get servicemonitor -A
kubectl get svc llm-Prefill-Decode-metrics -n scaling-system -o yaml
kubectl get endpoints llm-Prefill-Decode-metrics -n scaling-system
kubectl describe servicemonitor llm-Prefill-Decode-metrics-monitor -n monitoring
Focus on confirming:
- Whether Service is really associated with backend Pods.
- Whether endpoints is empty; if empty, means Service.selector cannot select Pods.
- Whether ServiceMonitor's namespaceSelector and selector.matchLabels match actual Service.
- Whether Prometheus instance only scrapes ServiceMonitor with specific labels.
5. InplaceScaling created successfully, but follower replica count not changed
Symptom description: RSG resource created successfully, modified leader resource replica count, follower replica count unchanged
Possible causes:
resourceNameinleaderFollowerConfiginconsistent withtargetResources[].name.- Follower target resource does not exist, or Controller cannot access.
- Target resource itself does not support adjusting replicas through
spec.replicas.
Recommended inspection:
kubectl describe resourcescalinggroup leader-follower-rsg -n scaling-system
kubectl get deploy scheduler worker sidecar -n production
kubectl logs -n scaling-system deploy/<rsg-controller-deployment>
Focus on confirming:
- Whether both
leaderandfollowercan find corresponding entries intargetResources. - Whether
followRatiooffolloweris expected value. - Whether errors like follower resource not found, patch follower replicas failed appear in logs.
6. After deleting RSG, business resources still exist
This is one of the expected behaviors of current implementation, especially for GroupReplication.
Reason explanation:
- When RSG is deleted, it will prioritize preserving business workloads to avoid directly interrupting business due to deleting control objects.
- What controller mainly cleans up is control plane artifacts such as snapshots and configurations, will not default to deleting all generated group resources for users.
Recommended handling:
- First confirm whether these resources still need to be kept.
- If no longer needed, can batch clean according to naming rules:
kubectl get deploy -n scaling-system | grep "-Prefill-Decode-"
kubectl get svc -n scaling-system | grep -- "-Prefill-Decode-"
Execute deletion after confirmation.
7. Upper-layer ElasticScaler, TidalScheduler or HPA not driving RSG to take effect
Symptom description: HPA modifies RSG's replicas field, but resource replica Pod count unchanged
Possible causes:
- Current RSG is actually InplaceScaling, not suitable as scale target.
- Upper-layer policy's targetRef does not correctly point to ResourceScalingGroup.
- Upper-layer controller itself not running normally.
- RSG's scale sub-resource read/write not successful.
Recommended inspection:
kubectl get resourcescalinggroup llm-Prefill-Decode-group -n scaling-system -o yaml
kubectl get --raw "/apis/autoscaling.openfuyao.com/v1alpha1/namespaces/scaling-system/resourcescalinggroups/llm-Prefill-Decode-group/scale"
kubectl logs -n scaling-system deploy/<elastic-scaler-or-tidal-deployment>
Focus on confirming:
- Whether
spec.scalingStrategy.typeisGroupReplication. - Whether
spec.replicasandstatus.replicasreturned byscalesub-resource meet expectations. - Whether errors like
target not found,update scale failedappear in upper-layer controller logs.
Licensed under the MulanPSL2
 YueGongWangAnBei No.44030002007300