AI Inference Elastic Scaling
Feature Introduction
Elastic Scaler is a general-purpose scaling decision framework designed to meet various scaling requirements across different business scenarios.
- Architecture-wise, Elastic Scaler adopts a plugin-based mechanism that supports flexible extension of user-defined scaling decision algorithms and custom resource management logic.
- Capability-wise, Elastic Scaler supports both metrics-driven and event-driven scaling semantics, with event-driven mainly serving business scenarios with significant fluctuations or sudden changes in resource demands.
Application Scenarios
Elastic Scaler is suitable for scenarios where various business services are deployed in Kubernetes cluster environments and require dynamic resource management, including:
- Dynamic Load Scenarios: Request volume fluctuates significantly over time, requiring dynamic adjustment of service instance numbers based on actual load.
- Cost Optimization Scenarios: Reduce resource costs and improve resource utilization through intelligent scaling while ensuring service performance.
- Mixed Load Scenarios: Business scenarios with mixed long and short requests and varying concurrency, requiring intelligent scaling based on request characteristics and instance status.
- Multi-tenant Scenarios: Multiple tenants share resources, requiring dynamic resource allocation based on each tenant's SLA requirements.
- PD Disaggregation Architecture: In Prefill-Decode disaggregation architecture, requires independent adjustment of resource allocation between P-side and D-side.
- Scale-to/from-zero Scenarios: Control workload start/stop based on external signals, used for on-demand resource usage.
- Explicit Replica Count Scenarios: Directly specify target replica count based on external state, used for scenarios requiring clear capacity targets such as tidal traffic or scheduled load switching.
Capabilities
- Supports deployment and usage in K8s clusters.
- Supports metrics-driven scaling (MetricsTrigger).
- Supports event-driven scaling (StateTrigger).
- Supports custom scaling algorithm plugin development.
- Supports custom resource plugin development (via ResourceScalingGroup).
- Compatible with K8s native HPA capabilities.
Notice:
- Custom algorithms can be successfully registered, but will not be invoked during actual scaling decisions in the current version.
- Custom algorithms in MetricsTrigger mode and External/ExternalServer metric types are currently unavailable in this version.
Key Features
- Plugin-based Architecture: Supports plugin-based integration of scaling decision algorithms, enabling users to flexibly define and evolve scaling algorithms based on business characteristics.
- Multiple Trigger Modes: Supports three types of scaling semantics: metrics-driven, event-driven (signal, state).
- Multi-metric System: Supports metrics from various sources (Resource, External, ExternalServer) as scaling decision inputs.
- Generic Resource Management: No longer limited to specific resource types, supports integration of any custom resource into the scaling system through Resource plugin mechanism.
- K8s Native Integration: Based on K8s HPA (Horizontal Pod Autoscaler) and custom resource extensions, fully compatible with the K8s ecosystem.
Implementation Principle
Figure 1 Component Architecture Diagram
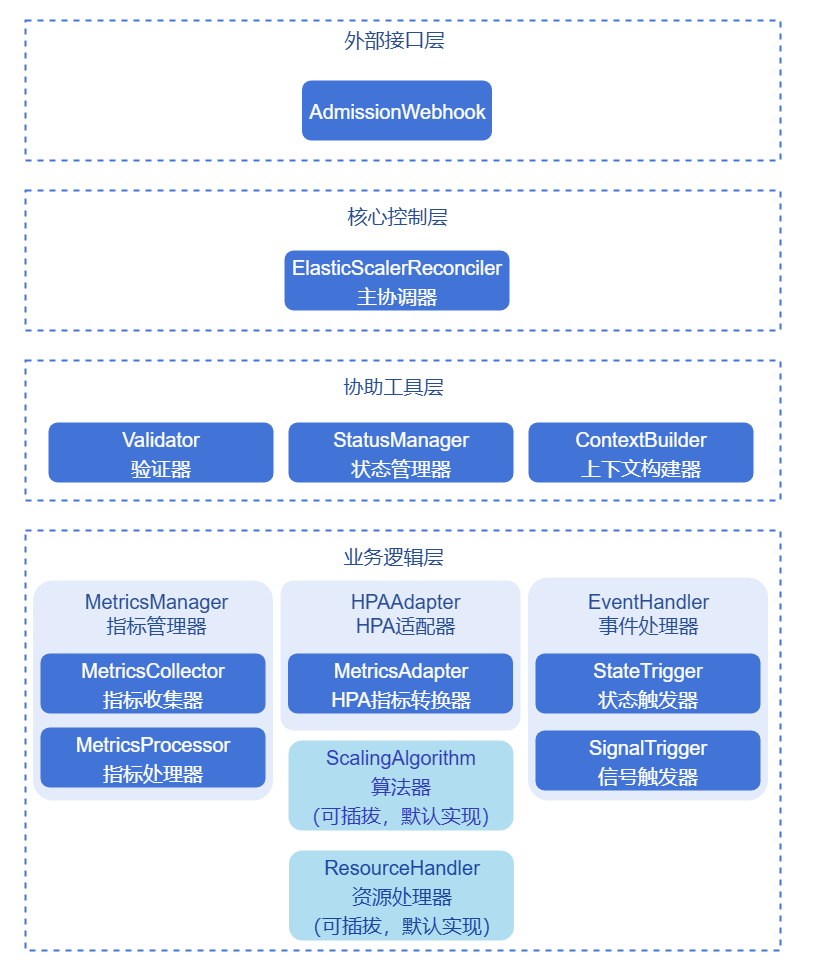
Figure 2 Component Deployment View
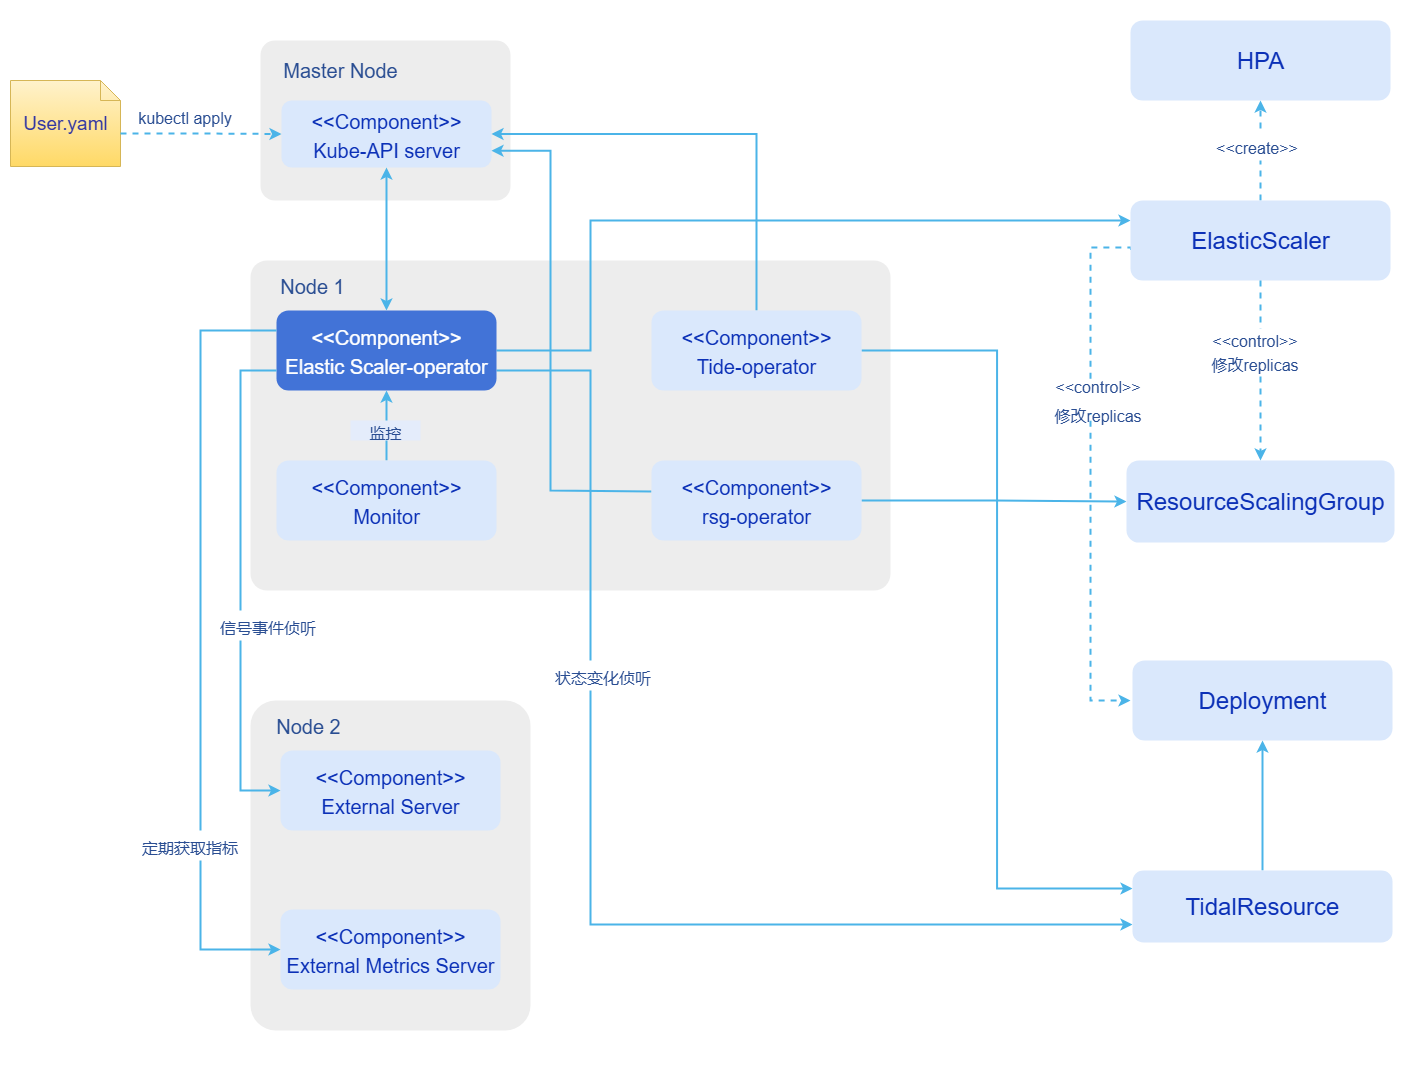
Elastic Scaler manages different types of scaling trigger sources through a unified Trigger abstraction. Based on the configured Trigger type, the framework selects different execution paths:
- MetricsTrigger (Metrics-driven): Elastic Scaler obtains real-time metrics from monitoring components, calculates the target replica count based on the configured scaling algorithm (HPA or custom algorithm), and then updates the target resource.
- StateTrigger (State-driven): Elastic Scaler listens to state changes of external resources, reads the
status.desiredReplicasfield of external resources, and applies this value to the target resource. Suitable for scenarios such as tidal traffic and scheduled load switching. The specific process is as follows:- External controller (such as Tidal) calculates the desired replica count and writes it to the
status.desiredReplicasfield of the external resource. - External resource binds to ElasticScaler through labels (
elasticscaler.io/namespaceandelasticscaler.io/name). - Elastic Scaler listens to state changes of external resources and reads the
status.desiredReplicasfield. - Elastic Scaler applies the desired replica count to the target resource.
- External controller (such as Tidal) calculates the desired replica count and writes it to the
- SignalTrigger (Signal-driven): Elastic Scaler listens to external signal endpoints, and upon receiving ScaleUp/ScaleDown signals, sets the target resource replica count to
maxReplicasorminReplicas. Suitable for on-demand resource start/stop scenarios.
Relationship with Related Features
- EagleEye: Compatible with near real-time monitoring metrics of inference services provided by EagleEye, including key metrics at different granularities such as business runtime, system runtime, and hardware health. Integration with EagleEye has not been implemented in the current version.
- Tidal: Compatible with the Tidal component. When using the tidal algorithm, Tidal expresses explicit capacity targets through the
status.desiredReplicasfield, and Elastic Scaler is responsible for execution. - ResourceScalingGroup: Compatible with ResourceScalingGroup CRD, uses custom resource plugins to integrate into the decision framework for fine-grained AI resource management.
Installation
This chapter introduces the methods of independently deploying Elastic Scaler in an existing cluster and deploying Elastic Scaler through InferNex suite integration.
Independent Deployment
This section introduces how to independently deploy Elastic Scaler in a K8s cluster with existing inference services and monitoring components.
Prerequisites
Before starting installation, please ensure the following conditions are met:
Environment Requirements:
- Kubernetes cluster: v1.28.0 or above.
- Cluster administrator permissions: Required for installing CRDs and cluster-level resources.
- Helm tool: Used to deploy Elastic Scaler and related components.
Hardware Requirements:
- Elastic Scaler itself has no special hardware environment requirements. As a lightweight controller component, it can run on standard x86 or ARM architecture nodes.
Installing Elastic Scaler
Execute the following command to install Elastic Scaler.
helm install elastic-scaler oci://cr.openfuyao.cn/charts/pd-orchestrator --version 0.0.0-latest \
  --set elastic-scaler.namespace.create=true # Default is false, if the cluster does not contain scaling-system namespace, this needs to be set to true.
Installs the pd-orchestrator chart from the OCI repository. This chart will install three components by default: ElasticScaler, RSG, and Tidal, and create a default RSG CR and ElasticScaler CR instance configuration.
If you currently only need to deploy the ElasticScaler Controller, it is recommended to explicitly disable other components and default example instances:
helm install elastic-scaler oci://cr.openfuyao.cn/charts/pd-orchestrator --version 0.0.0-latest \
  --set elastic-scaler.enabled=true \
  --set elastic-scaler.elasticScaler.enabled=false \
  --set resourcescalinggroup.enabled=false \
  --set resourcescalinggroup.instanceConfig.enabled=false \
  --set tidal.enabled=false
Note:
- When deploying Elastic Scaler, the monitoring data source and scaling target need to be correctly configured.
- ElasticScaler CR needs to configure the correct target resource (Deployment, StatefulSet, etc.) and Trigger configuration.
- For detailed scaling strategy configuration, please refer to the Configure Scaling Strategies section.
InferNex Integrated Deployment
InferNex is a one-click integrated intelligent routing, monitoring, and elastic scaling deployment suite that includes the elastic-scaler component internally.
Prerequisites
- Kubernetes v1.28.0 or above.
- At least one inference chip per inference node.
- At least 16GB memory and 4 CPU cores per inference node.
- Online installation can access the image repository: oci://cr.openfuyao.cn.
- User has permission to create RBAC resources.
Quick Installation of InferNex
InferNex can be independently deployed through the following two methods:
Obtain the project installation package from the openFuyao official artifact repository.
Install from remote repository.
bashhelm install infernex oci://cr.openfuyao.cn/charts/infernex --version xxxWhere
xxxneeds to be replaced with the specific project installation package version, such as0.21.1, andinfernexis the release name.Before executing the installation, please ensure:
- The cluster has created namespaces
istio-system(Istio Gateway resource must be deployed in this namespace) andscaling-system.
- The cluster has created namespaces
Obtain from openFuyao GitCode repository.
Pull the project from the repository.
bashgit clone https://gitcode.com/openFuyao/InferNex.gitInstallation and deployment.
Taking the release name
infernexas an example, execute the following command in the directory at the same level asInferNex:bashcd InferNex/charts/infernex helm dependency build helm install -n <namespace> infernex .
Configure Scaling Strategies
This chapter explains how to configure Elastic Scaler's scaling strategies for different business scenarios.
Metrics-driven Scaling (MetricsTrigger)
Metrics-driven scaling automatically adjusts replica count based on real-time metric changes, suitable for continuously running business scenarios with smooth load variations.
Using HPA Algorithm
The HPA algorithm scales based on CPU/memory utilization, leveraging K8s native HPA capabilities.
- In HPA algorithm mode, Elastic Scaler will automatically create and manage the corresponding Kubernetes HPA resource.
- If switching the scaling algorithm from HPA to other modes (such as custom algorithms), you must first delete the Elastic Scaler instance or manually clean up the generated HPA resources, otherwise resource management conflicts will occur.
- Elastic Scaler and managed resources (Deployment, StatefulSet, etc.) need to maintain a one-to-one mapping relationship.
- In HPA mode, Elastic Scaler and managed resources must be deployed in the same namespace.
apiVersion: elasticscaler.io/v1alpha1
kind: ElasticScaler
metadata:
  name: hpa-scaling-example
  namespace: ai-inference
spec:
  # Scaling target
  targetRef:
    apiVersion: apps/v1
    kind: Deployment
    name: vllm-inference

  # Min/max replicas
  minReplicas: 2
  maxReplicas: 10

  # Metrics-driven trigger configuration
  trigger:
    type: MetricsTrigger
    metricsTrigger:
      # Use HPA algorithm
      scalingAlgorithm: HPA

      # Metrics configuration
      metrics:
      - type: Resource
        resource:
          metricsName: cpu
          target:
            type: Utilization
            averageUtilization: 70
Table 1 HPA Strategy Parameter Description
| Parameter | Type | Description | Default Value |
|---|---|---|---|
type | string | Trigger type, must be set to MetricsTrigger. | - |
scalingAlgorithm | string | Scaling algorithm, set to HPA to use K8s native HPA. | - |
metrics[].type | string | Metric type (Resource/External), current version only supports Resource. | - |
metrics[].resource.metricsName | string | Resource metric name (cpu/memory). | - |
metrics[].resource.target.type | string | Target type (Utilization/Value/AverageValue). | - |
metrics[].resource.target.averageUtilization | int | Target average utilization (percentage). | - |
Using Custom Algorithm
Custom algorithm functionality in the current version only supports algorithm registration. Although the algorithm interface and registration mechanism have been defined, the core logic of the algorithm invocation path (AlgorithmManager.CalculateDesiredReplicas()) has not been implemented yet. It is recommended to use the HPA algorithm in the current version.
Custom algorithms allow users to develop custom scaling logic based on specific business requirements.
apiVersion: elasticscaler.io/v1alpha1
kind: ElasticScaler
metadata:
  name: custom-scaling-example
  namespace: ai-inference
spec:
  # Scaling target
  targetRef:
    apiVersion: apps/v1
    kind: Deployment
    name: vllm-inference

  # Min/max replicas
  minReplicas: 2
  maxReplicas: 10

  # Metrics-driven trigger configuration
  trigger:
    type: MetricsTrigger
    metricsTrigger:
      # Use custom algorithm
      scalingAlgorithm: xpa

      # Algorithm configuration
      algorithmConfig:
        threshold: 0.8
        cooldownSeconds: 60

      # Metrics configuration
      metrics:
      - type: External
        external:
          metric:
            name: qps
          target:
            type: AverageValue
            averageValue: "100"
Table 2 Custom Algorithm Strategy Parameter Description
| Parameter | Type | Description | Default Value |
|---|---|---|---|
scalingAlgorithm | string | Custom algorithm name (e.g., xpa). | - |
algorithmConfig | map | Algorithm configuration parameters, structure depends on algorithm implementation. | - |
metrics[].type | string | Metric type (Resource/External/ExternalServer), current version only supports Resource. | - |
metrics[].resource.metricsName | string | Resource metric name (cpu/memory). | - |
metrics[].resource.target.type | string | Target type (Utilization/Value/AverageValue). | - |
metrics[].resource.target.averageUtilization | int | Target average utilization (percentage). | - |
Event-driven Scaling (StateTrigger)
State-driven scaling triggers based on external resource state changes, suitable for scenarios requiring clear capacity targets such as tidal traffic and scheduled load switching.
apiVersion: tidal.io/v1alpha1
kind: Tidal
metadata:
  name: tidal-frequent-test
  namespace: ai-inference
  labels:
    elasticscaler.io/name: state-scaling-example
    elasticscaler.io/namespace: ai-inference
spec:
  targetRef:
    apiVersion: apps/v1
    kind: Deployment
    name: elastic-scaler-state-test   # Change to your Deployment name to scale
    namespace: ai-inference
  triggers:
    times:
      rules:
        - name: time1
          cron: "CRON_TZ=Asia/Shanghai 0 50 16 * * *"
          replicas: 3
          description: time1
        - name: time2
          cron: "CRON_TZ=Asia/Shanghai 0 0 8 * * *"
          replicas: 5
description: time2apiVersion: elasticscaler.io/v1alpha1
kind: ElasticScaler
metadata:
name: state-scaling-example
namespace: ai-inference
spec:
# Scaling target
targetRef:
apiVersion: tidal.io/v1alpha1
kind: Tidal
name: tidal-frequent-test
# State-driven trigger configuration
trigger:
type: StateTrigger
stateTrigger: {}Table 3 StateTrigger Parameter Description
| Parameter | Type | Description | Default Value |
|---|---|---|---|
type | string | Trigger type, must be set to StateTrigger. | - |
stateTrigger | object | State-driven configuration, currently an empty object. | - |
Event-driven Scaling (SignalTrigger)
SignalTrigger signal-driven scaling functionality has not been implemented in the current version. Related interfaces have been defined (SignalTrigger.HandleSignalTrigger()), but the core listening logic has not been completed yet.
Signal-driven scaling triggers scale-to/from-zero based on external signals, suitable for on-demand resource start/stop scenarios.
apiVersion: elasticscaler.io.io/v1alpha1
kind: ElasticScaler
metadata:
  name: signal-scaling-example
  namespace: ai-inference
spec:
  # Scaling target
  targetRef:
    apiVersion: apps/v1
    kind: Deployment
    name: vllm-inference

  # Min/max replicas
  minReplicas: 0
  maxReplicas: 10

  # Signal-driven trigger configuration
  trigger:
    type: SignalTrigger
    signalTrigger:
      endpoint: "https://webhook.example.com/scale-signal"
      protocol: https
Table 4 SignalTrigger Parameter Description
| Parameter | Type | Description | Default Value |
|---|---|---|---|
type | string | Trigger type, must be set to SignalTrigger. | - |
signalTrigger.endpoint | string | Signal endpoint address. | - |
signalTrigger.protocol | string | Communication protocol (http/https). | https |
Using Elastic Scaling
This chapter demonstrates how to view, monitor, and manage the scaling behavior of Elastic Scaler in the cluster.
View Scaling Strategies
# View all ElasticScaler resources
kubectl get elasticscalers -n <NAMESPACE>

# View specific ElasticScaler details
kubectl describe elasticscalers <SCALER_NAME> -n <NAMESPACE>
View Scaling Events
# View scaling events
kubectl get events -n <NAMESPACE> --field-selector involvedObject.kind=ElasticScaler

# View controller logs
kubectl logs -n <NAMESPACE> -l control-plane=<RELEASE-NAME>-elastic-scaler-controller-manager -f
Disable/Enable Scaling Strategy
Elastic Scaler disables scaling strategy by deleting CR and enables by creating CR.
# Disable scaling strategy (delete CR)
kubectl delete elasticscalers <SCALER_NAME> -n <NAMESPACE>

# Enable scaling strategy (create CR)
kubectl apply -f <elastic-scaler-config>.yaml
FAQ
- What types of metrics are supported?
Elastic Scaler currently only supports Resource (Kubernetes native resource metrics, e.g., CPU, memory) metric type.
- How to debug scaling strategies?
You can debug scaling strategies by viewing the Elastic Scaler's Controller logs and K8s events. The logs will contain detailed information about metric data, decision process, and scaling operations.
- How does StateTrigger work?
In StateTrigger mode, an external controller (such as Tidal) calculates the desired replica count and writes it to the status.desiredReplicas field of the external resource. Elastic Scaler listens to state changes of external resources, reads this field, and applies it to the target resource. External resources need to bind to ElasticScaler through labels elasticscaler.io/namespace and elasticscaler.io/name.
- How to develop custom scaling algorithms?
Custom scaling algorithms need to implement the ScalingAlgorithm interface and register the algorithm through the DefaultRegistry.Register() method. For detailed development guide, please refer to Plugin Development Guide.
Custom algorithm invocation path has not been implemented in the current version. Algorithms can be successfully registered, but will not be invoked during actual scaling decisions. It is recommended to use the HPA algorithm in the current version.
- How to support custom resource types?
By implementing the ResourceHandler interface and using the RegisterResourceHandler() method for registration, any custom resource type can be supported. Custom resources need to implement methods such as GetCurrentReplicas() and UpdateReplicas().
Licensed under the MulanPSL2
 YueGongWangAnBei No.44030002007300